Skip to content

Friday, 21 August 2026

I daily drove KDE Linux for almost a year and I liked it, but I'm also switching back to Fedora KDE. Here's my ramblings about it all.

KDE Linux is the hot new Linux distro from KDE themselves. At the moment it uses Arch Linux as it's base but with heavy modifications and changes. You can read more about it on the site, but to sum up: It's an atomic/"immutable" distro that does not have any kind of package management outside of installing flatpaks. (Do note that they're experimenting on using buildstream instead of Arch Linux.)

As one of the KDE devs I've been daily driving it on my desktop, which I use for both work and leisure (gaming).

The following text can be quite technical as I am viewing this through my developer workflow lense, though I will also touch on regular user things.

Upsides
My lizard fursona making an smile face.

For general purpose computing and KDE dev, things are looking great!

Honestly, it works rather well, considering the alpha status. And for development purposes, the nightly builds of the newest hottest stuff from our git repos is very nice: I don't have to build everything myself every morning.

Though there are some issues with that too: Sometimes the servers are not producing a new image, for reason or another, so I may end up building things myself anyway. Some other times, there is an image that just has some broken change in. Luckily in those situations I can just boot a previous image and use that.

What I really liked though was the systemd-sysext workflow. Sysext is a tool that allows me to layer my changes to the system on top of the previous stuff. So when the system is running /usr/bin/konsole it actually runs my self-built /home/akseli/Projects/kde/usr/bin/konsole. As far as the system is concerned, it's in the same path.

What we currently do in other distros is some environment flag magic to run things from the build-path, instead of /usr/bin/. It also works fine, but can be a bit more brittle, especially when testing something like a login manager.

The workflow is simple:

  • I build my changes to an app, Plasma desktop component, etc. using kde-builder.
  • I refresh the sysext with run0·systemd-sysext·--always-refresh=yes·refresh;
    • sudo works too, i use run0 because it has the popup so I notice it after a long build.
  • The changes are now live on my system!
    • Apps may need to be restarted sometimes of course.
    • If something goes wrong, I can just clean the sysext folder.

It feels more robust and easier to manage.

So on this front, KDE Linux has been really fun to work with. Perfect for testing and development of all the KDE Plasma stuff.

When it comes to applications from flatpaks, they usually work fine, but they can have the typical flatpak issues: Some app needs a permission to a folder that it can't see, so you have to turn off the app, add permissions, turn back on the app, yadda yadda. Apps that use XDG portals properly usually work fine, though there's a bug somewhere in the stack that when the system updates (the atomic image of the OS changes), the portal forgets the folder paths and you have to reopen the file for the path to refresh.

When it comes to gaming stuff, Steam Flatpak has worked really well. I have not noticed any issues compared to the native package. Same with Bottles, all has been just fine and nice. Though sometimes there has been bugs with running games, such as games not locking your cursor properly, but they're often gone with the next update as more people spot these bugs now.

Downsides
My lizard fursona making an sad face.

With anything more complex than what the system is intended for, things get difficult.

As an atomic distribution, it is expected that any dev tools that are not already installed on the machine, such as your favorite terminal tools or text editors, you will have to either to download them from the internet like a Windows user (plop the binary in ~/.local/bin), or use Distrobox/Kapsule/Toolbox... etc.

Container workflow feels cumbersome to me most of the time. For KDE work, since all the tools to build and run applications are already installed on the system, it's rather effortless. But when I want to continue a game project like my Artificial Rage game project, I would have to enter a distrobox, install all the things, then edit and build the application inside that container. And when I switch a project, it's expected I create a new container for that, and so on.

I don't really like that. I prefer my tools to just be available on the host so I can run them without messing with containers: I have bad memory and am terrible with context switching, so I keep forgetting changing or creating containers.

What I did instead was create bunch of dumb scripts called dbi that are a wrapper for installing tools and "exporting" them from the distrobox so I can use them on host without having to enter them. By exporting I mean they use the distrobox-export command that creates a symlink to your ~/.local/bin with the app name, so you can just run them from terminal like always.

It's not ideal, but it works. Sadly this comes with a performance deficit when running programs like eza, which is ls alternative that shows icons. I like my little icons. :) When running eza directly on host, it runs immediately, but when using the distrobox version, it will take 1-2 seconds, which gets surprisingly annoying when going through folders. No idea if that could be improved somehow, but the speedbump is likely from the part where it enters the container.

This reveals the larger downside: Lack of "blessed" package management, especially for commandline applications.

I have tried multiple tools, but all of them had some issues:

  • Brew, while had great user experience, would sometimes overtake the system python installation and break kde-builder
    • I don't know if this has been fixed? I have not dared to try.
  • Coldbrew, which has similarly nice user experience, but the package versions can be hit or miss
  • Nix, which is very overcomplicated for this usecase and the user experience is just annoying
    • It works, but you will have to remember to garbage-collect and whatnot every time you update apps
    • Fixable with a nice wrapper, I think
    • However some claim this is "not the Nix way" so I'm left here wanting something this tool can do but is not meant for?

Which left me with always just using distrobox and accepting the performance and UX penalty.

Another thing I miss is having KMail and KOrganizer just installed on my system, talking with my digital clock applet so when I click on it, I would see my calendar event. It's very small thing, but it's huge quality of life feature for me. The Kontact flatpak can't do that, and it's sadly really broken in general.

Lastly, as I work on the Union style engine, flatpak applications will not see the Union styles yet. This means I will have either to build a separate KDE platform for it myself using the CI, which can be super slow. Especially if I have to build it multiple times to see the changes. I can build some apps myself but more complex ones such as KMail will take a lot of time for me. This is where I miss just installing an app from dnf on Fedora, as it can just use the styles on my computer, as the app is also installed on the host like the Union style is.

Regular use and my use

For regular user, who plays video games and uses a web browser and never really touches terminal, I think KDE Linux will do very fine, especially when it starts having stable releases that do not update every night. At it's current iteration, it's more a developer tool than something I would recommend for regular user, unless you're super enthusiastic or have spare machines.

But me, being the nerd that writes blogposts about Linux and KDE that I am, I like having more control over the system. I don't mind having all my dev tools cluttered on my host system. (However if it touches NPM, it's going into a container. Luckily I rarely have to bother with that.) And in general, atomic distributions can be rather opinionated: If those don't match your view of the distribution, it can be hard to get along as you can't really modify it for your usecase. (Yes I know about ostree.)

So I would say that the more complicated your usecase gets and if you need tools that are not already in the base system, it can get quite cumbersome.

So that's why I'm switching back to Fedora KDE: It gave me all the control I needed. I will likely stil use flatpaks for almost all apps on my machine though, as I do find sandboxing rather useful at times.

I highly encourage anyone who wants to test newest KDE stuff to run KDE Linux on a VM or a secondary machine. I will keep using KDE Linux on my laptop as there I don't have so many different needs, and I want to just install the new shiny stuff from git, not build on it, as building anything on that laptop is super slow.

This whole thing has also made me realise something..

My lizard fursona making an smile face.

All distros have their own strenghts, weaknesses and tradeoffs. It's all about choosing what works for you and your system.

My desktop system will benefit from Fedora KDE, but my laptop will benefit from KDE Linux.

I will keep observing how the story of KDE Linux develops. I may try it again on my desktop later, we will see.

Some of you reading might ask: "But why Fedora KDE?"

It's one of the nicest distros I've used when it comes to KDE stuff. The people working on Fedora KDE are some of the nicest folks I've met with, and they work very closely with KDE upstream. Fedora KDE follows KDE releases really closely so it feels like I'm always on current release, making the development workflow very easy.

Thanks for reading!

ps. Friend sent me this and I cackled like a hyena.

Dumb meme about me liking the popup more than security features

Thursday, 20 August 2026

The last two weeks were spent polishing the mobile-friendly selection mode based on Marco Martin's review feedback, wrapping up the multi-select work that's been the focus since weeks 9 and 10.

Selection Mode Refinements (!46)

The first version of Selection Mode had a few issues. The checkbox was not properly aligned with the entry text, so I changed the delegate to use a RowLayout. This keeps the checkbox directly next to the label and vertically centered.

Marco Martin also suggested that the whole row should be clickable, not just the checkbox. I moved the selection logic into a shared page.toggleSelection() function and used it for both mouse and touch taps. This makes selection work the same way on both devices.

For the toolbar, only "Delete Selected Secrets" and "Exit Selection Mode" should be available during selection mode. I added visible: !page.selectionMode to the other actions so they are completely hidden, including from the overflow menu.

OLE-Dispatch When Doing MFC/Qt Migration

Most people who have ever ported an application from MFC to Qt know that at some point they have to integrate a QWidget into an MFC part of the user interface. Or the other way around, but that's a different story. Normally you would simply use a QWinWidget for that to do exactly what you want. But what happens if your application created the old MFC window as an OLE Control Extension (OCX)? In that case the easiest solution is to intercept the control name and provide it to your own factory providing the correct widget, which can then be embedded in a QWinWidget. Or you could use plugins to stick to the idea of it being DLLs. All roads lead to Rome. But what if your OLE based application uses the OLE-Dispatch way of initializing the controls? Setting properties, invoking methods, and so on?

I had exactly that problem and came up with a solution which glues OLE's IDispatch interface together with Qt's QMetaObject. That means you can access your QWidget's (or any other QObject) properties via the IDispatch interface provided by my QObjectDispatcher class. They only need to be declared via Qt's Q_PROPERTY macro. The same applies to slots and methods marked with Q_INVOKABLE.

Let's see how this is being used:

// This is the widget we're working with:
QWidget* someWidget = ...;

// Lets' create our dispatcher:
// You have to delete it yourself or let COM do it for you via IUnknown::AddRef/Release
QObjectDispatcher* dispatcher = new QObjectDispatcher(someWidget);

// The code until this point is the only part which is new in your application, as
// far as dispatching the calls/properties is involved. From here, it's exactly the same;
// from the OLE MFC application's perspective we often only have an IUnknown:
IUnknown* pUnknown = dispatcher;

// Now get the interface and start playing with it:
CComQIPtr<IDispatch> pDispatch(pUnknown);

// First we have to retrieve the index of the property we change
LPOLESTR name = "windowTitle";
DISPID dispId = -1;
pDispatch->GetIDsOfNames(IID_NULL, &name, 1, LOCALE_SYSTEM_DEFAULT, &dispId);

// Now that we have the index, we change the property
VARIANT varTitle = CComVariant("New window title");
DISPSPARAMS dispParams = { nullptr, nullptr, 0, 0 };
dispParams.rgvarg = &varTitle;
dispParams.cArgs = 1;
pDispatch->Invoke(dispId, IID_NULL, LOCALE_SYSTEM_DEFAULT, DISPATCH_PROPERTYPUT,
    &dispParams, nullptr, nullptr, nullptr);

As you can see the API of IDispatch is not fun to work with and there's no reason to use this except of making that kind of stuff work in existing MFC/OLE-applications while porting. I strongly advise against using it in new code.

How does that work? Well, the IDispatch interface works in two steps. First, you have to request the ID of the method/property you want to access via GetIDsOfNames. You can request several IDs at the same time. QObjectDispatcher traverses the methods of the handled QObject via the corresponding QMetaObject. It then returns the index of the method. If there’s no method found, it checks for a property. If it’s found, it returns the index of the property plus the number of methods, to be able to recognize the type afterwards. If neither a method nor a property by that name is found, an error is reported.

Let’s have a short look at how GetIDsOfNames roughly works. That example code cannot be used directly but gives you a rough idea of the implementation:

HRESULT QObjectDispatcher::GetIDsOfNames(REFIID riid, LPOLESTR* rgszNames, UINT cnames, LCID, DISPID* rgDispId)
{
    // GetIdsOfNames supports requesting several at the same time
    for (uint i = 0; i < cNames; ++i) {
        // note you cannot use QMetaObject::indexOfMethod directly, 
        // since it expects the fully qualified name
        auto indexOfMethod = []() { /* ... */ };
        const int methodIndex = indexOfMethod(rgszNames[i]);
        if (methodIndex != -1) {
          rgDispId[i] = methodIndex;
          continue;
        }
    }
    // now do the same for the properties...
    // [...]
    return S_OK;
}

In the second step you can call Invoke to either invoke a method or to access a property. For this you need to pass a struct DISPSPARAMS which contains the arguments. rgvarg is an array to several arguments which are stored in reverse order. QObjectDispatcher will now pick the method or property (depending on the id passed and whether you passed DISPATCH_PROPERTYPUT, DISPATCH_PROPERTYGET, or DISPATCH_METHOD) and call it. For this it has to translate the arguments. For method calling, they need to be translated to QMetaMethodArgument or QMetaMethodReturnArgument for the return value. For properties, we have to go through QVariant to be able to read/write the property via Qt’s Meta Object System.

Let’s also have a look at how Invoke works internally. Even here, this code piece is not complete and won’t work directly:

HRESULT QObjectDispatcher::Invoke(DISPID dispIdMember, REFIID riid, LCID, WORD wFlags, DISPPARAMS* pDispParams, VARIANT* pVarResult, EXCEPINFO*, UINT*)
{
    if (wFlags == DISPATCH_METHOD) {
        const QMetaMethod method = metaObject->method(dispIdMember);

        // translate return argument
        auto returnArgument = translateReturnArgument(method, pVarResult);

        // then call the method, translating all the arguments
        invokeMethod(method, m_object, returnArgument, translateArgument(0), ...);

        return S_OK;
    }

    // [...]
}

So, in your application, which expects a CWnd generated by some factory, you do the following:

  • Create a wrapper CWnd which you actually return to the caller. This CWnd will in some way provide access to an IDispatch instance like it was doing before your port
  • Create a QWinWidget residing inside of the CWnd.
  • Put your portedQWidget into the QWinWidget
  • Create a QObjectDispatcher working on your ported QWidget
  • Make your CWndreturn this QObjectDispatcher as IDispatch

Now your application should threat your ported widget as it was never ported. Of course, you have to provide the same properties and methods as the system expects using Qt's Meta Object System (Q_PROPERTY, Q_INVOKABLE).

There are, of course, some limitations:

  • You cannot overload names of methods as OLE doesn't allow that
  • Optional parameters are not supported, as QMetaMethod doesn't reflect that (or I simply haven't figured out, who knows…)
  • You have to provide a type-mapping for the argument types. The example project linked below provides only IUnknown*, int, and QString as these are the most common ones and show how it works
  • The example solution is not thread-safe

Find the complete code as a little example project on KDAB's GitHub repository at: https://github.com/KDABLabs/blogs-qt/tree/main/MFC-Migration-OLE-Dispatch

The post OLE-Dispatch When Doing MFC/Qt Migration appeared first on KDAB.

Animation on Android and new Transform Tool and Color Sampler features? Read on for a look at development news and the Krita-Artists forum's featured artwork from last month.

Development Report

Krita 5.3.3 Released

Krita 5.3.3 was released with various fixes as well as revamped Android supporter donations.

Developments in Krita Plus

Animation rendering on Android is now possible, via MediaEncoder and LibAV. (change by Carsten Hartenfels)

Support for the XCF file format native to GIMP has been removed, as the xcftools library that was used is long outdated and unmaintained. It's recommended to instead use GIMP to load XCF, and use the OpenRaster (.ora) interchange format for exchanging files between programs. (change)

Some font-related crashes at startup have been fixed. (bug; change 1, change 2 by Wolthera van Hövell)

The new menu options on Android for interface scaling and supporter options not appearing if toolbars had previously been customized has been fixed. (change by Carsten Hartenfels)

A crash when redoing joining and then deleting paths with the Edit Shapes tool has been fixed (bug; change by Elena Sagalaeva), as well as deleting subpaths deleting the wrong ones due to shifted indices (bug; change by Luna Lovecraft). Additionally, path segments can now be deselected with Shift-click (change by Luna Lovecraft).

Developments in Krita Next

The Transform Tool's Liquify mode has a new mode. "Restore Shape" undoes previous distortions while keeping the new position of a shape, and optionally keeping the rotation, scale, and stretch. (change by Moritz Staudinger)

Using the Transform Tool to rotate, distort, and move a triangle, then using Restore Shape to remove the distortions while keeping the new rotation, position, and scale.

The Color Sampler can now show a zoomed in preview in order to precisely pick a pixel, when using the circle color preview. This "Zoom Preview (Pixel-Perfect Color Sampler)" option is in preferences under General->Cursor alongside the option to switch between the circle and rectangle preview. (change by Đạt Lê)

Using the zoomed color sampler preview to pick Kiki's eye color from the Krita 5.3/6.0 splash artwork without zooming in on the entire image.

Various HDR metadata can now be saved into .kra files and viewed in Image Properties. This HDR metadata will also be used when rendering animations. (change by Wolthera van Hövell)

Community Report

July 2026 Monthly Art Challenge Results

The winner of the "An Imaginary Friend" challenge is…

Join This Month's Art Challenge!

For August's Kiki-focused theme, last month's winner has chosen "Kiki's Epic Adventure". The optional challenge is to create separate assets for textures or repetitive elements and paste them into the scene. Build up Kiki's story and take us on a dramatic adventure!

This month's featured forum artwork, as voted in the Best of Krita-Artists - June/July 2026:

Participate in next month's nominations and voting to voice your opinion on the Best of Krita-Artists - July/August 2026.

Krita is Free - But You Can Contribute!

Krita is free to use and modify, but it can only exist with the contributions of the community. A small sponsored team alongside volunteer programmers, artists, writers, testers, translators, and more from across the world keep development going.

If this software has value to you, consider donating to the Krita Development Fund. Or Get Involved and put your skills to use making Krita and its community better!

Krita's mascot Kiki putting money in a piggy bank

Additional Changes

Krita Plus (Stable, 5.3.4/6.0.4-prealpha):

  • Text Tool: Fix a crash when using the SVG text editor's editing actions (Undo, Redo, Cut, Copy, Paste). (bug; change by Luna Lovecraft)
  • Wide Gamut Color Selector: Fix color preview popup appearing in the wrong place and not disppearing when the docker is borrowed into the Pop-up Palette or toolbar Docker Box. (bug; change by Luna Lovecraft)
  • Filters: Fix the Color Adjustment filter dialog's curve point controls not working until switching channels. (change by Moritz Staudinger)
  • Assistant Tool: Fix toggling show/hide assistants not taking effect until the canvas is interacted with. (bug; change by Luna Lovecraft)
  • File Formats: Don't show data loss warnings when exporting, since it doesn't affect the original file, and don't warn about inability to save selections, since they are expected to be temporary. (change 1, change 2, by Carsten Hartenfels)
  • General: Add icons for convert, selection modifier, and close actions. (change 1, change 2, change 3, by Arkady Flury)
  • Python Plugins: Comics Manager: Fix a huge memory leak on export, partially re-add exporting vector panels and text, and other small fixes. (bug; change by Wolthera van Hövell)

Krita Next (Unstable, 5.4.0/6.1.0-prealpha):

  • Color Management: Set default display rendering intent to RelativeColorimetric. (change by Dmitry Kazakov)
  • Assistant Tool: Show assistants' custom colors at the bottom of their editors to distinguish them. (change by Carsten Hartenfels)
  • General: Add an option to show or hide icons in menus, or keep the platform default, in preferences under General->Window. (change by Timothée Giet)
  • General: Add icons for 10 brushes and 10 scripts actions, and add an action for Ten Scripts. (change by Arkady Flury)

Nightly Builds

These pre-release versions of Krita are built every day.

Note that there are currently no Qt6 builds for Android.

Get the latest bugfixes in Stable Krita Plus (5.3.4/6.0.4 prealpha): Linux Qt6 Qt5 — Windows Qt6 Qt5 — macOS Qt6 Qt5 — Android arm64 Qt5 – Android arm32 Qt5 – Android x86_64 Qt5

Or test out the latest Experimental features in Krita Next (5.4.0/6.1.0-prealpha). Feedback and bug reports are appreciated!: Linux Qt6 Qt5 — Windows Qt6 Qt5 — macOS Qt6 Qt5 — Android arm64 Qt5 – Android arm32 Qt5 – Android x86_64 Qt5

Wednesday, 19 August 2026

I have been working on integrating Btrfs snapshots into KDE software. The central part of this work has been realized in the form of KIO Snapshot, which has just been released. Here I want to discuss what it is, how it works, how it was developed, and the surrounding work across KDE.

Background

Among the key features of Btrfs is the ability to take efficient snapshots of subvolumes

. They are efficient because Btrfs makes snapshots share file extents with the originals, so snapshots only take up additional space where they differ from the original. Thus it is cheap to take snapshots frequently without worrying about disk space.

This can be used to build very handy universal “undo” or “time travel” functionality for the user. Yet, though there are graphical tools to work with Btrfs snapshots such as Btrfs Assistant, these are separate from normal file browsing, and are rather technical tools concerned with the orchestration of snapshots. Direct integration of snapshots into the file browser itself for mundane end-user purposes, like Windows has with Previous Versions or macOS with the famous Time Machine, has been lacking in the Linux world. The aim of KIO Snapshot is to build that kind of direct integration for KDE.

What it is

KIO Snapshot lets Dolphin (indeed any KDE software) list and access Btrfs snapshots of a file or subvolume.

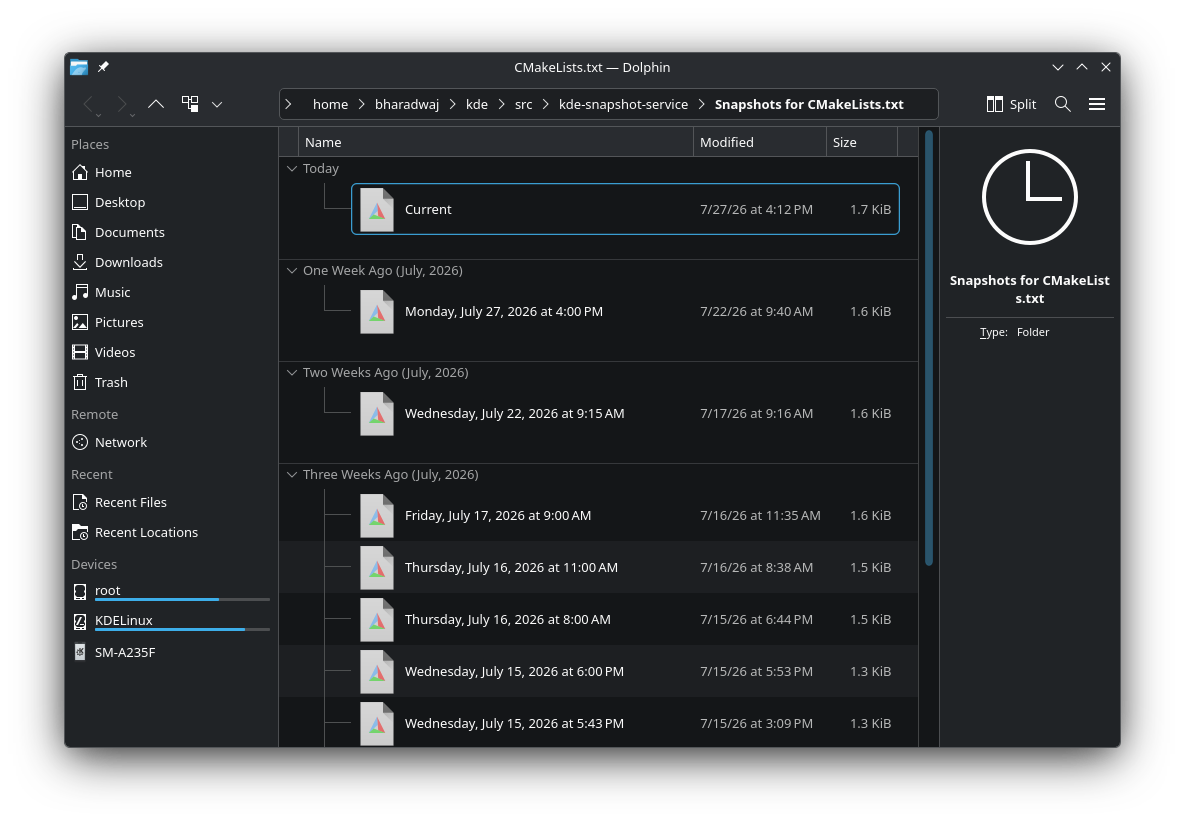
You can right-click on a file and go to a folder view showing you all the distinct past versions of it as saved in your snapshots. ​ (At first, I wrote the snapshots-for-file case as a dialog with buttons to open or restore (like Windows’ Previous Versions feature), but I changed it to be a full virtual folder, since that would be much more flexible — now a user could select multiple previous versions and open them in a comparison tool, or copy them somewhere, or check their metadata easily, or whatever else they wished.) 

Screenshot showing the filesnapshots KIO worker, listing the versions of a file

You also have views into entire directory trees of subvolumes at their various snapshots.

Screenshot showing the snapshot KIO worker, listing the snapshots of a subvolume

Note that it does not take snapshots, it only allows access to them. To take snapshots, you would have to do it manually, or through an orchestrator like Snapper

.

How it works

Mainly it uses libbtrfsutil from btrfs-progs to talk to the filesystem, and KDE Frameworks’ Solid to query filesystems and mounts on a more meta level.

Now, the Btrfs API is quite conservative in what it allows non-superusers to do with it. Even a question as seemingly innocuous as “what subvolume is this path in?” cannot be answered for a non-superuser directly. The consequence of this is that on my first attempt at building this integration, I had one component running as a system-level DBus service which would let users query stuff like this for files they owned.

Luckily, a nudge from Méven Car made me realize that with some working-around, I could build out all the features without anything running as root. For example, while Btrfs is loath to let you get the subvolume ID for a path or vice versa, it will happily give you a listing of the subvolumes (that you can access) under a path. From there you can derive all the information needed.

Using this, KIO Snapshot implements a KIO worker that provides the snapshot:// protocol, which will be understood by all programs which use KDE Frameworks. This protocol provides a virtual view into the snapshots in a filesystem along two dimensions: the snapshots for a given subvolume, each of which is a browsable directory tree in itself; and the snapshots for a given file across all snapshots of its containing subvolume.

Allied work

Aside from KIO Snapshot itself, I also worked on some small things in other parts of KDE to support it.

  • Fixed a bug in KIO which caused inconsistent behavior in Dolphin’s location bar: KIO MR #2305
  • Fixed how Solid handled Btrfs layouts like the one used in KDE Linux: Solid MR #261
  • Special default view settings for KIO Snapshot’s views in Dolphin: Dolphin MR #1347
  • Experimented with adding support for Btrfs subvolumes into Solid itself — this is just a rough proof-of-concept, and maybe this work is more appropriate further upstream in UDisks — but here it is anyway: Solid branch btrfs-subvolumes

KDE Linux

KDE Linux will soon ship with Snapper and KIO Snapshot out-of-the-box.

Hadi Chokr did a lot of excellent integration work here: migrating the filesystem layout to make all user homes subvolumes, and automatically integrating and configuring Snapper for all users seamlessly.

This is part of a broader initiative in KDE Linux to improve data backup and restore systems, which has also overseen improvements elsewhere, such as in the Kup backup system.

Release

The first stable release of it was made today (thanks to Bhushan Shah for helping with the release process). I imagine it should be getting packaged into distros fairly soon, thanks to the infrastructure that comes with being a KDE project, but even then it should be easy enough to compile from source. Please use it and report bugs and requests, thank you!

I want to share from the server a directory, and use that directory share on the client computer. Using the Microsoft Windows "Server Message Block" (SMB)/CIFS directory sharing protocol.
I have created two Kubuntu 26.04 virtual machines: a Samba server and a Samba client.

Samba server: 192.168.122.202. Computer name: ASERVER. User name: sadmin.
Samba client: 192.168.122.92. Username: administrator.

A video version of this tutorial is available https://www.youtube.com/watch?v=mNgBZtunNnE .

1.Configure the Samba server computer

Kubuntu 26.04 by default uses the ufw firewall solution and ufw is disabled. Configuring a firewall is another topic.
Create the directory /home/sadmin/smbshare . Put some files there.
# Become the user root.
sudo su
ufw status
# Says "Status: inactive".
apt update
apt install samba smbclient
cat << 'EOF' >> /etc/samba/smb.conf

[linux_smbshare]
   comment = Linux smbshare
   path = /home/sadmin/smbshare
   browseable = yes
   read only = no
   guest ok = no
   valid users = sadmin
   create mask = 0660
   directory mask = 0770
EOF
testparm
systemctl restart smbd
smbpasswd -a sadmin
# I use the same password for the user sadmin. Both for the
# Linux user account and for the Samba user account.
pdbedit -L
# Stop being the user root.
exit
smbclient //localhost/linux_smbshare -U sadmin
ls
# Exit smbclient shell/REPL.
exit
Note that two parts of NETBIOS protocol are disabled by default: the one similar to DNS (hostname to IPv4 conversion) and the one where the Samba server advertises itself on the Local Area Network (LAN) as an SMB server.
testparm
says:
[global]
        disable netbios = Yes
Bonus points if the Samba server computer has an IPv4 address that does not change.
Restart the Samba server computer.

2.Configure the Samba client computer

sudo apt update
sudo install smbclient cifs-utils avahi-utils
The information that, years ago, we could get using the NETBIOS protocol can now be accessed from a Samba client computer using other technologies:

* When listing SMB servers on the LAN. Instead of using NETBIOS. We can use the DNS-Based Service Discovery (DNS-SD) protocol (avahi).
$ smbtree -N
main: This is utility doesn't work if netbios name resolution is not configured.
If you are using SMB2 or SMB3, network browsing uses WSD/LLMNR, which is not yet supported by Samba.
SMB1 is disabled by default on the latest Windows versions for security reasons. \
It is still possible to access the Samba resources directly via \name or \ip.address.

$ avahi-browse -rtp _smb._tcp
+;virbr0;IPv4;ASERVER;Microsoft Windows Network;local
=;virbr0;IPv4;ASERVER;Microsoft Windows Network;local;aserver.local;192.168.122.202;445;
* Converting from "ASERVER" to an IPv4 address does not work. Converting from "ASERVER.local" to the IPv4 address 192.168.122.202 works because of avahi DNS-SD DNS server/client, mdns4_minimal.
$ ping ASERVER
ping: ASERVER: Temporary failure in name resolution
$ ping ASERVER.local
PING ASERVER.local (192.168.122.202) 56(84) bytes of data.
64 bytes from 192.168.122.202: icmp_seq=1 ttl=64 time=0.110 ms
$ cat /etc/nsswitch.conf | grep hosts
hosts:          files mdns4_minimal [NOTFOUND=return] mymachines dns
# Continue configuring the Samba client.
sudo mkdir -p /media/192_168_122_202_linux_smbshare
# Without file with SMB username and password.
sudo mount -t cifs //192.168.122.202/linux_smbshare /media/192_168_122_202_linux_smbshare \
-o username=sadmin,uid=administrator,gid=administrator
sudo umount /media/192_168_122_202_linux_smbshare

# With file with SMB username and password.
# As the user administrator.
cat << 'EOF' > /home/administrator/.smbcredentials
username=sadmin
password=pass123
EOF

sudo mount -t cifs //192.168.122.202/linux_smbshare /media/192_168_122_202_linux_smbshare \
-o uid=administrator,gid=administrator,credentials=/home/administrator/.smbcredentials

sudo mount /media/192_168_122_202_linux_smbshare
sudo umount /media/192_168_122_202_linux_smbshare
Append to /etc/fstab the line:
//192.168.122.202/linux_smbshare /media/192_168_122_202_linux_smbshare cifs noauto,uid=administrator,gid=administrator,credentials=/home/administrator/.smbcredentials 0 0
Note that "//192.168.122.202/linux_smbshare" will not be mounted automatically because of "noauto" in /etc/fstab.
Each time you reboot your Samba client computer and want to use the shared directory, run:
sudo mount /media/192_168_122_202_linux_smbshare
Advantages: if the Samba server is down or configured incorrectly or if the network connection between Samba server computer and Samba client computer is not great. The Samba client computer will not be affected.

3.I test the KDE app smb4k

https://apps.kde.org/smb4k is a KDE GUI app that acts as an SMB client. It can list SMB servers available on the LAN. It can determine the "SMB domain" of a computer. It can get the list of shared directories. It can list the contents of shared directories. It can mount a shared directory using "mount.cifs".
kde-builder smb4k
kde-builder --run smb4k
I have encountered some issues:

A. If server is Kubuntu 26.04, smb4k cannot get the list of shares of the SMB server. https://invent.kde.org/network/smb4k/-/merge_requests/24
This is because "ping ASERVER" does not work, but "ping ASERVER.local" works correctly.

B. In smb4k when hovering on top of a SMB server, a tooltip is shown that says "Workgroup: LOCAL" instead of "Domain: WORKGROUP".
From the command line, we can get the correct "SMB domain" for an SMB server:
$ rpcclient -U % -c "lsaquery" 192.168.122.202
Domain Name: WORKGROUP
Domain Sid: (NULL SID)
A fix for this issue is more complicated because each time dnssd/kdnssd notifies smb4k that an SMB server named A exists on the LAN. smb4k should decide if this computer was received previously. If not, smb4k should run the command line above and get the "actualDomain" from the STDOUT of the process. Bonus points if getting the correct SMB domain is non blocking, creates at most 5 "rpcclient" sub processes at the same time.

Improving Effect Widgets for Kdenlive

Organization: KDE Community

Project: Kdenlive

Contributor: Yash Bavadiya (@xevrion)

Mentor: Jean-Baptiste Mardelle (@mardelle)

Reviewers: Julius Künzel (@jlskuz), Bernd Jordan (@bjordan)

This is the final post for my Google Summer of Code 2026 project with KDE. Full weekly detail is linked at the bottom; this one's the complete summary.

Contents

Project overview

Kdenlive's effect system exposes powerful underlying libraries (libavfilter, MLT) through custom Qt widgets in the effect panel. Three of those widgets had real, longstanding usability gaps: the Curves effect needed the same filter applied three separate times for independent RGB channel control, the Gradient Map effect only supported two fixed color stops when the underlying MLT filter supports up to 32, and the Time Remapping panel had no way to ease speed changes, every transition was abrupt.

The goal of this project was to rebuild all three as proper, well-tested widgets, backed by the correct underlying data formats, with full backward compatibility for existing project files.

Project status

The project is fully complete. All three proposed widgets are merged into Kdenlive's master branch:

  • Curves (!887), merged, shipping in Kdenlive 26.08
  • Gradient Map (!911), merged (JB merged manually after a GitLab auto-merge issue, shows as "Closed" in the MR list but the code landed with commit b0b678c6)
  • Speed Ramp (!928), merged

One follow-up item remains open: a bug found during Speed Ramp review, where keyframe interpolation types are lost when a clip is resized, was traced to ClipModel::requestRemapResize() in the timeline model, outside this project's original scope. My mentor asked for this as a separate follow-up MR rather than folding it into !928, since it touches unfamiliar timeline code with roughly 15 mutation sites needing updates. That fix is in progress.

Pre-GSoC work

Before the coding period began (community bonding ran April 30 to May 24), I landed twelve merged contributions to Kdenlive, mostly while getting familiar with the codebase and building trust with the maintainers:

  • !824: added missing HD-ready (1366×768) project profiles at standard frame rates
  • !827: fixed duplicate profiles appearing in the New Project dialog, root cause was two compounding bugs, MLT shipping spec-duplicate profile files, and refresh() being called twice, breaking naive deduplication
  • !826: added common video/audio/image MIME types to the desktop file, so Kdenlive appears as an option in file manager "open with" menus
  • !831: added configurable clip type colors (video, audio, title, image, slideshow) to the Colors and Markers settings page
  • !835: fixed broken tab order in the Render dialog
  • !837: added an "Identify Gaps" feature to the Timeline menu, detecting empty spans across all video tracks and placing guide markers, went through several rounds of feedback from Eugen Mohr and Bernd Jordan
  • !853: added a warning before deleting tracks that contain clips
  • !857: added tests for guide position preservation across fps changes
  • !858: detect embedded subtitle streams and display the count in clip properties
  • !859: snap the playhead to snap points when dragging in the ruler
  • !874: added a "return playhead to start position on stop" setting
  • websites/planet-kde-org!292: added this blog to Planet KDE

This is also where I learned the project's review culture firsthand, small, focused MRs, clear commit messages, and genuine back-and-forth before merge, which set the tone for everything that followed.

Coding-period deliverables

1. Curves widget

MR !887, closing #2187

Replaced a single shared curve control with per-channel tabs (All, R, G, B) for the avfilter.curves effect. Previously, independent per-channel adjustment required applying the effect three separate times.

What changed:

  • Each channel is a separate av_curve XML parameter, so the model stores per-channel state directly rather than in a widget-side cache. This went through a real architecture revision: my first version combined all channels into one compound parameter, JB pointed out this would be hard to extend later, and I refactored to separate parameters per his suggestion, closer to how m_mainKeyframeWidget already worked elsewhere in the codebase
  • Fixed a libavfilter segfault triggered by control points placed too close together on the x-axis, replaced an initial reject-the-update guard with point snapping, per Bernd Jordan's suggestion that silently rejecting user input would be confusing
  • Removed an inherited 5-point limit that only applied to frei0r.curves, not the new avfilter.curves path
  • Added optional per-channel colors, a reset button scoped to the active channel, editable input/output spinboxes for the selected point, and a GIMP-style ghost overlay showing other edited channels
  • 48 unit tests in tests/avcurvetest.cpp

2. Gradient Map widget

MR !911, closing #1064, relating to #2206

Replaced a fixed two-color-stop gradient control with a draggable multi-stop editor for the gradientmap MLT filter, which already supported up to 32 stops via stop.N parameters, the UI just never exposed them.

What changed, including a real architecture pivot:

  • First version was a fully custom-painted widget, add/remove/drag stops, min 2 max 32, live QLinearGradient preview
  • Julius Künzel suggested looking at the Qt-Color-Widgets library for design inspiration, with an eye toward eventual KDE Frameworks upstreaming. I initially wired in the actual vendored library as a dependency
  • JB and Julius reviewed that approach and decided against it, Kdenlive shouldn't depend on another external library. The direction became: reimplement the specific behaviors as original code, using the library only as a UX reference, not a dependency
  • Reverted the vendor linkage, restored the original from-scratch widget, and added the missing pieces (alpha-channel checkerboard preview, native QStyle frame styling) as new, independently-written code
  • During review, JB found the gradient rendering as a flat, empty rectangle under Breeze's style, root cause was draw order, the native frame primitive was painting its interior background after the gradient fill. Fixed by drawing the frame first, then the gradient inside its content rect
  • Added a model-layer 32-stop cap (independent of the widget-level cap, so a hand-edited project file can't bypass it), fixed a barely-visible handle on dark stops, and added an RGBA hover tooltip
  • A known limitation surfaced late in review: MLT's gradientmap filter doesn't actually support alpha in its gradients, an upstream MLT issue, not a bug in this widget. JB merged anyway to make the 26.08 window, tracked as a pre-26.08.0 fix
  • 8 unit tests, expanded to full widget-interaction coverage, 27 assertions total

3. Speed Ramp widget

MR !928, relating to #2188 and #1454

Added per-keyframe interpolation types to the Time Remapping panel, so speed changes can ease in and out instead of switching abruptly at every keyframe boundary, plus a curve band showing the actual interpolated shape.

What changed, including the biggest scope revision of the summer:

  • The original proposal described free-draggable bezier handles on the remap timeline. Investigation before writing any code found that MLT has no bezier keyframe type to serialize a time map into, only preset easing types
  • Checked with JB, free bezier handles in MLT had already been investigated years earlier and found difficult to integrate. Direction became: reuse Kdenlive's existing keyframe type system (the same one used for volume, brightness, and other effects) instead of inventing something new
  • Found KeyframeCurveEditor, an existing widget that samples MLT's true interpolated value per pixel and draws it in a plain QWidget, as the reference pattern
  • Verified empirically, with a standalone C test program against the real MLT build, that non-linear keyframe types are genuinely honored during playback, not just valid syntax, and found a real gotcha: the type suffix must be on the segment's starting keyframe, not the ending one, or it's silently treated as linear
  • Implemented per-keyframe type storage, MLT-native serialization via anim_set/serialize_cut, a per-pixel sampled curve, and a type selector, four clean commits
  • Julius and Bernd raised real usability concerns after testing: the UI mixes time remapping (position-based) and speed keyframing (rate-based) as mental models, without making the distinction clear. JB proposed a longer-term fix, splitting Time Remap and Speed Ramp into two distinct UI modes using MLT's speed_map parameter. Scoped this with JB directly: implemented the two smaller, well-defined pieces immediately (expanding the type list from a curated 4 to the full 13, moving the selector into the toolbar), and opened issue #2231 to track the larger mode split as a post-GSoC follow-up
  • While implementing the type-list expansion, found and corrected an assumption from the earlier review discussion: tested directly against MLT and confirmed the old pre-selector behavior serialized as linear, not "discrete" as had been suggested, Discrete is a genuinely different freeze-then-jump behavior
  • JB later reported a resize bug, keyframe types lost when a clip is resized. Traced the root cause through two incorrect hypotheses (each one investigated with real evidence and honestly ruled out) before finding it: ClipModel::requestRemapResize(), timeline-side code outside this MR's original files, flattens the time_map string during resize without preserving type suffixes. Scoped as a separate follow-up MR per JB's request

Also merged during GSoC

!878: added a "Duplicate Clip" action to the timeline (Ctrl+D, right-click menu), addressing a long-standing feature request (bug 435319). Not one of the three proposal widgets, but real merged work from the same period. During review, JB found and removed two stray method declarations left over from a rebase error, a good reminder to double check rebase output carefully.

Challenges

The recurring theme this summer was discovering, partway through implementation, that an assumption baked into the original plan didn't hold, and needing to change direction with a mentor rather than push forward regardless.

The Gradient widget's dependency pivot is the clearest example: a reviewer's suggestion to look at an external library led to actually wiring it in, before the maintainers weighed the tradeoffs and decided against the dependency entirely. The Speed Ramp widget had a similar moment at a lower level, discovering MLT genuinely couldn't support the originally proposed bezier-handle design, verified with a real test program rather than assumed.

The most useful habit that came out of this was treating claims, my own included, as things to verify rather than trust. The Speed Ramp resize bug took three separate investigation passes to actually locate, the first two hypotheses were reasonable but wrong, and each was only ruled out by tracing the actual call sites and reproducing the bug directly rather than reasoning about it abstractly. The bug was eventually found in code outside the original three files this project touched.

Future work

  • requestRemapResize fix: the resize bug described above, scoped as its own MR, in progress
  • Time Remap / Speed Ramp mode split: tracked in #2231, a larger UI rework splitting position-based and rate-based remapping into two distinct modes, deferred by mutual agreement with JB given the time remaining
  • MLT gradientmap alpha support: the upstream MLT limitation flagged during Gradient widget review, needs a fix or an explicit UI restriction before Kdenlive 26.08.0 final

None of these block the core functionality already merged. All three proposed widgets are in master and working.

Acknowledgements

Thanks to Jean-Baptiste Mardelle, my mentor, for consistently thorough review across all three widgets and for being willing to change direction, twice, on real architectural questions, when new information came up, rather than defending an earlier decision for its own sake. Thanks to Julius Künzel for the UX instincts that reshaped the Gradient and Speed Ramp widgets for the better, and to Bernd Jordan for close, careful review on every MR and for sketching out concrete alternatives when something wasn't working. Genuinely a great summer.

All the weekly posts

Full status report and week-by-week technical detail also on the KDE Community Wiki.

Linux Magazine discusses Tellico in their September 2026 issue, in an article titled Let’s Collect, which covers Tellico, Recoll, Asunder, and Picard, among others.
In this article we’re looking at Linux applications that you may want to try out if you already have a collection of physical books, ebooks, CDs, or other media, or are just starting to collect. You can create a catalog that stores metadata of your collection items, index ebooks to make their content searchable, and rip CDs so that you can play them on the computer, too.

The author, Hans-Georg Eßer, favorably mentions saving separate collection files for each type (books, coins, discs, etc.) which is nice. He does directly mention the Internet Search dialog, so I’m glad to see that the UI adjustments were effective. He even goes as far as showing fetch results from three different sources in the screenshot! The capability to drag an image into the Entry Editor was noted, which I appreciate. An extended section covered importing from CSV, which does seem to be functionality that just about every user needs at some point. His explanation of the process is much better than mine.

One of the gotchas that the article mentions is the .tc file extension was not automatically added to the saved file name. I suspect the author might not have been using the Plasma-desktop, or at least, not the KDE file integration, since the save dialog is supposed to have an option to do just that. So for the next release, I’ll automatically append .tc if there is no extension selected. That issue has popped up in other reviews, too.

Linux Magazine has mentioned Tellico a few other time, including June 2025 and as far back as August 2005.

Tuesday, 18 August 2026

Nextcloud provides a large public PHP interface to developers to use for building their application. It is commonly called OCP. Some of big components of OCP are the HTTP stack with IRequest, Response and Controllerto handle requests, the IQueryBuilder/IDBConnection to query the database and many feature oriented components and utilities.

Outside of OCP, applications can also use a lot of private APIs and 3rd party libraries included by Nextcloud, but these don’t have the same stability guarantees as the official public interface.

With Nextcloud Hub 26 Summer (35.0.0), there are 3 big changes coming to the OCP API. The first two are that we are now providing a public API for the Symfony Console component and the Doctrine database schema abstraction. The first one is required when wanting to extend the Nextcloud command line tool occ and the second one is used to create database migrations. Both are very important but would break every app every time we would update the dependencies, which is forcing us to keep older versions of these dependencies (thankfully older versions are still maintained).

Declaring Commands with #[AsCommand]

To replace the first one, we added a new family of PHP attributes and interfaces. Instead of inheriting from OC\Core\Command\Base to implement a command, you can now use a simple PHP invokable class and annotate it with the #[AsCommand] (link) attribute as follows.

#[AsCommand(
 name: 'app:create-user',
 description: 'Creates a new user.',
 help: 'This command allows you to create a user...',
 usages: ['bob', 'alice --as-admin'],
)]
class CreateUserCommand {
 public function __invoke(): ExitCode {
 // ...
 return ExitCode::Success;
 }
}

Options and arguments for your commands can be defined declaratively in the __invoke method parameters.

The parameter’s type and default value decide whether the argument or option is required, repeatable, or a flag.

#[AsCommand(name: 'app:user:created')]
class CreateUserCommand {
 public function __invoke(
 #[Argument(description: "The username of the user")]
 string $userId,
 #[Option(description: "Force the creation")]
 bool $force = false,
 ): ExitCode {
 // ...
 return ExitCode::Success;
 }
}

Additionally it is possible to inject IOutput and IInput in the __invoke method parameters to be able to ask questions; print texts, progress bars and tables.

This new API doesn’t replace the existing private API, which is still available, but using it allows you to improve the coverage of the static analyser as stubs for these commands are available in the nextcloud/ocp package and this will prevent you from API breakage when using the Symfony Console API directly.

Manipulating SQL Tables with OCP\DB\Schema

This is actually a small breaking change, but for the schema migration, ISchemaWrapper won’t return Doctrine\DBAL types anymore but instead our own wrapper in OCP\DB\Schema.

The wrapper has essentially the same API as the doctrine implementation so the breaking change should be minimal. But there are a few cases which won’t work anymore, for example:

  • Type hinting methods with a DBAL type where the type needs to be replaced with the new OCP type or use a union type if you want to support multiple versions.
  • Type::lookupName($column->getType()) -> $column->getType()->getName()

Fortunately all these issues should be found quite easily by installing your application, which should be the case when running your unit tests. Grepping for DBAL and running psalm/phpstan should also help find the issues.

Introducing the Nextcloud ORM

The third big change is the addition of a simple ORM to Nextcloud: OCP\AppFramework\ORM.

This allows you to define an easy mapping between your database tables and PHP objects by using PHP attributes. This can be used for simple tables.

<?php
use OCP\AppFramework\ORM\Attribute\Column;
use OCP\AppFramework\ORM\Attribute\Entity;
use OCP\AppFramework\ORM\Attribute\Id;
use OCP\DB\Schema\ColumnType;

#[Entity(name: 'twofactor_backupcodes')]
final class BackupCode {
 #[Id]
 #[Column(name: 'id', type: ColumnType::Integer, nullable: false)]
 public ?int $id = null;

 #[Column(name: 'user_id', type: ColumnType::String, length: 64, nullable: false)]
 public string $userId;

 #[Column(name: 'code', type: ColumnType::String, length: 128, nullable: false)]
 public string $code;

 #[Column(name: 'used', type: ColumnType::Smallint, nullable: false, default: 0)]
 public int $used = 0;
}

Which can then be fetched by using a Repository which provides convenient utilities to fetch, delete, update or insert entries in the database.

<?php
class BackupCodeRepository extends Repository {
 public const string entityClass = BackupCode::class;

 /**
 * @return \Generator<BackupCode>
 */
 public function findByUser(IUser $user): \Generator {
 return $this->findBy([
 'userId' => $user->getUID(),
 ]);
 }

 public function deleteByUser(IUser $user): void {
 $this->deleteBy([
 'userId' => $user->getUID(),
 ]);
 }
}

$backupCodeRepo = Server::get(BackupCodeRepository::class);

$backupCode = new BackupCode();
$backupCode->userId = 'admin';
$backupCode->code = 'secret';
$backupCode = $backupCodeRepo->insert($backupCode);

$backupCode->code = 'new-code';
$backupCodeRepo->update($backupCode);

$adminCodes = $backupCodeRepo->findBy(['userId' => 'admin']);

$backupCodeRepo->delete($backupCode);

The ORM also supports mapping simple relationships between tables. For example, to define a relation between a customer and a cart where each cart has a customer and each customer has a cart, you can use the following annotated PHP classes. In the background, Nextcloud will create a SQL query with a JOIN automatically to fetch all the information in one query.

#[Entity(name: 'repository_customer')]
final class Customer {
 #[Id]
 #[Column(name: 'id', type: ColumnType::Bigint)]
 public ?int $id = null;

 #[OneToOne(targetEntity: Cart::class, mappedBy: 'customer')]
 #[JoinColumn(name: 'cart_id', referencedColumnName: 'id')]
 public ?Cart $cart = null;

 #[Column(name: 'name', type: ColumnType::String, nullable: false)]
 public string $name;
}

#[Entity(name: 'repository_cart')]
final class Cart {
 #[Id]
 #[Column(name: 'id', type: ColumnType::Bigint)]
 public ?int $id = null;

 #[OneToOne(targetEntity: Customer::class, invertedBy: 'cart')]
 #[JoinColumn(name: 'customer_id', referencedColumnName: 'id')]
 public ?Customer $customer = null;
}

For now, this only supports OneToOne and ManyToOne relationships between classes, with OneToMany and ManyToMany still missing.

A good example how this simplifies the code is this pull request porting the oauth2 app to this entity system.

Improved HTTP dispatcher

The HTTP dispatcher which takes care of calling the correct controller method now does various levels of input sanitization based on the PHPDoc comments. This means you can now write the following and have some guarantees about some of your variables:

<?php

class MyController extends OCSController {
 /**
 * @param non-empty-string $search
 * @param positive-int $limit Maximum number of results to return
 * @param non-negative-int $offset Offset for searching
 * @return DataResponse<Http::STATUS_OK, list<CoreAutocompleteResult>, array{Link?: string}>
 *
 * 200: Autocomplete results returned
 */
 #[NoAdminRequired]
 #[ApiRoute(verb: 'GET', url: '/autocomplete/get', root: '/core')]
 public function autocomplete(string $search, int $limit = 10, int $offset = 0): DataResponse {
 // $search is now guaranteed to be non empty
 // $limit is now guaranteed to be > 0
 // $offset is now guaranteed to be >= 0
 ...
 }
}

You can also inject backed enums and the values for this parameter will be restricted to one of the enum values.

<?php

enum GrantType: string {
 case AuthorizationCode = 'authorization_code';
 case RefreshToken = 'refresh_token';
}

class MyController extends OCSController {
 #[PublicPage]
 public function getToken(
 GrantType $grant_type, ?string $code, ?string $refresh_token,
 ?string $client_id, ?string $client_secret,
 ): JSONResponse {
 ...
 }
}

These two changes make it easier for you to ensure your APIs are secure by default!

Other Small Changes

  • We now expose the PHP polyfill in the nextcloud/ocp which makes it easier for the tooling to pick them up. For example, you can now use the PHP 8.6 \SortDirection enum in your applications while PHP 8.6 is not even out yet. And we also added support for this enum in the IQueryBuilder::addOrderBy method.

  • OCP\DB\ColumnType as a modern enum replacement for the OCP\DB\Types which is a proper PHP enum and not a class with public constants.

What Is Coming Next?

In the next releases, I want to make Data Transfer Objects (DTO) even more powerful in Nextcloud. The new Entity classes are good examples of DTOs, as they are used to transfer data. What is still missing is a good strategy to serialize/deserialize them to JSON (and other formats) and also to validate them.

For this goal, we would want to wrap the already existing components from Symfony and just provide our own attributes. For reference, here’s what this looks like in Symfony, and what I’d really like to see in Nextcloud at some point.

use Symfony\Component\Validator\Constraints as Assert;
use Symfony\Component\Serializer\Attribute\Ignore;
use Symfony\Component\Serializer\Attribute\Context;
use Symfony\Component\Serializer\Normalizer\DateTimeNormalizer;

class Author {
 #[Assert\Email(
 message: 'The email {{ value }} is not a valid email.',
 )]
 protected string $email;

 #[Context([DateTimeNormalizer::FORMAT_KEY => 'Y-m-d'])]
 public \DateTimeImmutable $createdAt;

 #[Ignore]
 public function isPotentiallySpamUser(): bool { ... }
}

Monday, 17 August 2026

GSoC 2026 • digiKam • Post 3: The Benchmark, and the Fine-Tuning Decision

At the end of my last post I promised a comparison: Qwen2.5 against TinyLlama on real digiKam queries. This is that post. It grew a third model along the way, and the result surprised me enough that I want to walk through it honestly, because the tidy expectation I started with turned out to be wrong.

If you’re just joining: in the first post I introduced the goal - bringing natural-language search to digiKam, so you can find photos by describing them in plain English instead of filling in an advanced-search form. In the second post I walked through actually wiring a local LLM into a desktop app, and the lesson that surprised me: the model was the small part, and the pipeline around it: the prompt, the parser, the dictionary that catches ambiguity, did most of the real work. This post picks up the thread I left there: is the model I chose actually the right one?

The question underneath all of this is a practical one. digiKam’s natural language search runs a local, quantized model on the user’s own machine, no cloud, no API, your photos and your queries never leave your computer. That constraint is the whole point of the feature, and it’s also what makes model choice hard. You can’t just reach for the biggest, best model; it has to load and run on an ordinary laptop, next to digiKam itself, fast enough that a search doesn’t feel broken. So the real question isn’t “which model is best,” it’s “which model is the right balance for this job.”

I’d been running Qwen2.5-1.5B this whole time because it felt right. This post is me actually checking.

What I measured, and how

I built a small benchmark harness. It lives in core/tests/llm/, it’s a standalone Python script, and it does three things for every query: measures latency, measures peak memory, and scores structured-output accuracy, whether the model produced the correct search constraints.

The one thing I cared about most was fidelity: the benchmark had to test the real pipeline, not a convenient approximation of it. So it uses the exact prompt digiKam sends, transcribed straight from SearchPromptBuilder, and it feeds the model the same way the C++ backend does, as a raw prompt with no chat-template wrapping. If the benchmark and the app disagreed on how they talked to the model, the numbers would be fiction.

The test set is about 40 hand-labelled queries. Each one pairs a plain-English request with the constraints it should produce: “photos from 2023 rated 5 stars” should give a date range and a rating. I scored at the level of the model’s raw intent, before the resolver’s later cleanup steps, because I wanted to measure the model, not the pipeline wrapped around it.

Which brings me to the first thing I got wrong.

The benchmark caught my own mistakes first

My first run scored Qwen at 66%. I almost believed it.

Then I read the failures, and most of them weren’t the model. They were me, in the labels. I’d written that “pictures tagged sunset” should produce tag with the operator contains; the model produced eq; and when I checked the actual code, digiKam’s tag matching ignores the operator entirely and looks the tag up by name. So the model was right, my expected answer was wrong, and my benchmark was confidently marking a correct output as a failure.

There were a handful like that. A caption operator I’d mislabelled. And a latency problem that turned out to be the harness, not the model: I was letting the model generate all the way to its token limit, when the real backend stops the moment it has a complete JSON object. The model had been producing a correct answer and then rambling on past it; the app already knew to stop reading, and my benchmark had forgotten to. It was the same “knowing when to shut up” issue from last post, except this time the mistake was mine, in the harness. Once I fixed it to stop at the first complete object the way the backend does, median latency dropped from about 15 seconds to under 2.

I’m telling you this because it’s the most important thing the benchmark did. Before it could measure the model, it measured my assumptions, and several of them were wrong. A benchmark that only ever confirms what you expected isn’t measuring anything. The 66% was noise; the real signal was underneath, once I stopped trusting my own labels and started checking them against what the code actually does.

The honest Qwen2.5-1.5B number, after fixing my labels, is about 85%.

The three-way comparison

I benchmarked three models, all as Q4_K_M quantized GGUFs so the comparison is fair, all getting the identical prompt:

  • TinyLlama-1.1B, the lightweight baseline.
  • Qwen2.5-1.5B, the model I’d been using.
  • Qwen2.5-3B, added because I wanted to know: would a bigger model be better?

Here’s what came back:

ModelConstraint accuracyMedian latencyPeak RAM
TinyLlama-1.1B18%~6.4s~1.3 GB
Qwen2.5-1.5B85%~2.3s~2.0 GB
Qwen2.5-3B79%~29s~3.5 GB

I sat with that middle-and-bottom row for a while, because it’s not what I expected.

Natural language search demo

TinyLlama can’t do the job

At 18%, TinyLlama isn’t close. And it’s not failing gracefully, it’s failing weirdly. It invents field names. It puts typos in values ("accpeted"). In several queries it copied the schema template literally into its output, the null | { ... } placeholder and all, producing JSON that doesn’t parse. It’s a small model being asked to do something structured, and it mostly can’t hold the shape.

The pattern makes sense once you think about capacity. With only 1.1B parameters, TinyLlama doesn’t have enough of a grip on the instruction to commit to one clean answer, so it hedges by generating more - more tokens, more variations, more noise. That also explains the thing I’d assumed wrong: I expected it to at least be faster, and it wasn’t. It was slower than the 1.5B model, precisely because it rambles; it doesn’t know when to stop, so it burns tokens generating garbage after the answer. Smaller model, worse latency, far worse accuracy. There’s no axis on which it wins.

And bigger didn’t help

This is the row I keep coming back to. I added Qwen2.5-3B expecting it to be the accuracy ceiling, the “here’s what you get if you’re willing to pay for it” option. Instead it scored lower than the 1.5B model, 79% against 85%, and it did it while taking thirteen times longer per query and using most of another gigabyte and a half of RAM.

The accuracy drop surprised me until I read the failures. The 3B model over-thinks simple structured tasks. On queries the 1.5B got right cleanly, the larger model would elaborate, add an extra constraint, reformat, second-guess, and break the exact match in the process. It even fumbled a couple of person queries the smaller model handled without blinking. More capacity, spent making a simple task complicated.

And the latency alone disqualifies it. A median of 29 seconds, with the first query taking 73, is simply not something you can put behind an interactive search box. Nobody types “red label photos” and waits half a minute. Even if the 3B had been more accurate, this number would have ended the discussion.

So the comparison brackets the choice from both sides. Too small can’t do it. Too big is slower, heavier, and no better, sometimes worse. The 1.5B model sits in the middle and wins on the two things that actually matter together: accuracy and speed. It’s not a compromise between them; it’s genuinely the best on both among viable options.

Where Qwen still gets things wrong

85% isn’t 100%, and the 15% is worth looking at, because it decided the next question.

Qwen’s errors aren’t scattered. They cluster, tightly, in two places. Orientation: it reads “portrait” as a subject tag rather than an image orientation, and it doesn’t map “horizontally” to “landscape.” And date structure: occasionally it uses the wrong operator on a date range. That’s essentially it. Everything else, ratings, labels, people, places, albums, composite queries with three constraints at once, it handles reliably.

And here’s the thing I already knew before the benchmark, now confirmed with numbers: those exact weak spots are the ones the pipeline already handles. Take the “portrait” slip. The model tags it as a subject; but SearchCapabilityDictionary recognises “portrait” as an ambiguous orientation term and maps it to the right field, and SearchIntentResolver validates the whole constraint before anything runs. The model’s mistake never reaches the search. The model’s blind spots and the pipeline’s safety net line up almost perfectly, which is a good sign that the pipeline was built around the right risks.

The question I actually had to answer: fine-tune or not?

My proposal left a decision open for this stage. If the benchmark turned up a recurring class of errors that prompting couldn’t fix, I’d spend the time on a lightweight LoRA fine-tune, curate a dataset, train an adapter on Qwen2.5-1.5B, convert it back to GGUF, and re-benchmark. If prompting was already good enough, I’d document that and spend the time on polish instead.

The 3B result is what settled it, and settled it more cleanly than I expected.

The residual errors, orientation and dates, are the same in the 3B model as in the 1.5B. Doubling the parameters didn’t fix them. That tells me something specific: these aren’t a capacity problem. If they were, a bigger model would have done better on exactly these cases, and it didn’t. They’re a prompting and vocabulary problem, “portrait” is genuinely ambiguous, “horizontally” is genuinely non-standard, and the fix for that kind of thing is a clearer prompt and a dictionary entry, not more model.

And I already have both. The prompt rules and the dictionary already catch these cases downstream in the real system. So a LoRA would be training a model to fix errors that a bigger model also makes, that aren’t about model size, and that the pipeline already handles.

There’s a second cost, too, beyond the missing benefit. A fine-tune isn’t free to keep. It means maintaining a curated training set, retraining every time the base model updates, and re-running the GGUF conversion each time, real ongoing overhead for the project. For a problem that a prompt line and a dictionary entry already solve, that complexity isn’t justified.

So: no fine-tuning. Not because I ran out of time, but because the evidence says it wouldn’t help. That feels like the right kind of conclusion to reach, the one backed by the data rather than the one I assumed going in.

One more thing the benchmark showed

There’s a category of query where every model, including Qwen, “fails” on paper, and I want to be clear about why that’s fine.

Ask any of these models, on their own, to handle “videos longer than 5 minutes” (a field digiKam’s search didn’t support at the time) or “asdfghjkl” (nonsense), and they guess. They invent a constraint. The raw model does not know how to say “I can’t do that”, small models are famously bad at refusing, and I wrote about that in the last post too.

But in the actual system, the model never gets the last word. The parser whitelists every field, so an invented field is rejected, not executed. The dictionary flags ambiguity. The model proposing something wrong and the system accepting it are two different events, and the whole architecture exists to keep the second one from happening. The benchmark scoring these as model-level failures is correct, and it’s also exactly why the layers around the model are there. A model you can’t fully trust is fine, as long as nothing downstream trusts it blindly.

Key takeaways

  • The middle model won. For structured extraction on a CPU, 1.5B was the sweet spot: too-small couldn’t hold the format, too-big was slower and no more accurate. Bigger is not automatically better.
  • Check your benchmark before you trust it. My first run scored 66%; most of the failures were wrong labels of mine, not model errors. A benchmark measures your assumptions first.
  • Match the app exactly. Same prompt, same raw inference, same stop condition. A benchmark that talks to the model differently from the app is measuring a different system.
  • The errors that remain aren’t a capacity problem. A 2x-larger model made the same orientation and date mistakes, which is how I know they’re prompting issues, already handled, and not something fine-tuning would fix.
  • No LoRA, on purpose. The decision my proposal left open is now closed by evidence: prompting plus the dictionary is sufficient, and the benchmark data says so.

Where things stand

The model choice is validated, with numbers behind it now instead of a hunch. The benchmark is in the tree at core/tests/llm/, with the dataset, a runner script, and a results write-up, so anyone can reproduce it or extend it with new queries. To run it yourself, see the README there. It’s the kind of thing the next person to touch this feature will be glad exists, which is the whole reason it’s committed rather than living in a notebook on my laptop.

What’s next

  • More search properties. Video duration, frame rate, bitrate, and file format, the fields the model didn’t map yet. (I’ve since started adding these, and they extend the same way every existing field did: a prompt rule, a dictionary entry, a parser whitelist, and a branch that writes the search field.)
  • User documentation. A natural-language-search section for the digiKam handbook, so the feature is discoverable by the people it’s actually for.
  • Polish and merge. Readying the branch for the 9.2.0 release, so this can go out to real users for beta testing.