Skip to content

Saturday, 27 June 2026

In my last post on Android platform integration I had suggested increasing the focus on Linux on mobile phones, due to Google’s ongoing attempts to close down Android for us. I have to follow that myself then of course, starting with looking at the situation around location/positioning.

What we have

The positioning stack looks roughly as follows as far as KDE applications are concerned:

  • Geoclue collects positioning data from various sources (GNSS receiver, cell modem, online service, etc) and provides a D-Bus API for it.
  • XDG Desktop Portal has a Location API for exposing this to sandboxed applications, including permission handling. XDG Desktop Portal itself uses Geoclue as its source.
  • Qt Positioning provides the application-facing API for retrieving position data, and QLocationPermission provides the API for requesting permissions when running sandboxed.

There’s two main gaps here though:

  • Qt Positioning only has a Geoclue backend, not one for the XDG Desktop Portal Location API. This means we wont have access to positioning information in a sandbox.
  • Qt’s entire permission API has only a dummy implementation on Linux, meaning it will always claim all permissions have been granted, which isn’t true in a sandbox.

What I couldn’t look into is whether Geoclue is able to actually retrieve GNSS data on “real” hardware, lacking access to devices to test this on.

Developer Tooling

Testing GNSS code with real hardware is rather inconvenient anyway, you have to move around for this, and quite a bit even when you also want to test various edge cases. Much better would be a way to inject arbitrary GNSS data low enough in the stack.

Many years ago I had built something like this for GammaRay, but that works on the level of Qt Positioning, which is above the parts we want to test here. Fortunately Geoclue offers us a way to do this as well. It’s looking for _nmea-0183._tcp mDNS services that provide a NMEA 0183 feed, and will use that as a source for GNSS data.

NMEA 0183 is a decades-old serial port protocol for GNSS equipment, easy enough to implement. As there are more usecases for this below, there’s now a small library setting up such a services, announcing it via mDNS and sending NMEA 0183 messages. NMEA 0183 defines two dozen or so different message types, but since Geoclue only looks at GGA and RMC ones those are all we need.
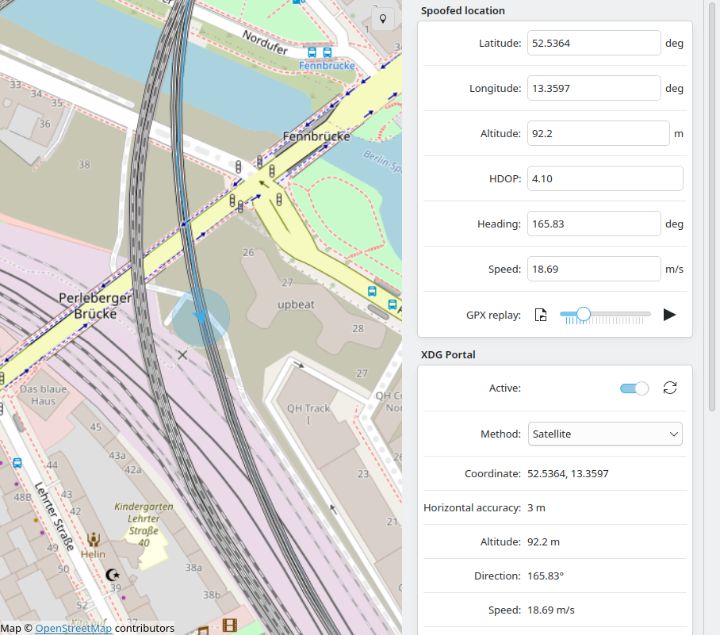
Screenshot of a map view showing a GPX track replay on the left and simulated and received position data in text form on the right.
XDG portal location spoofing tool.

Then all we need is a little GUI on top of this to select inputs on a map and have that fed into Geoclue. As a bonus we also have GPX track replay, so you can get a continuous feed of position updates automatically. The code is here.

XDG Portal plugin for Qt Positioning

Being able to “move” around the world from the convenience of my desk/couch made it then easy to implement the main missing piece here, connecting Qt Positioning to the XDG Desktop Portal Location API. The code is here, it’s just a couple of D-Bus calls and a bit of boilerplate needed for positioning plugins.

It’s registered with a higher priority than the Geoclue plugin and will be skipped if the portal API is not available.

QPermission API

That still leaves the permission handling. Qt’s API for that lives in Qt Core, so we cannot just implement support for XDG protal permissions there, as that needs dependencies from higher up in the stack, such as D-Bus and window ids.

There’s an easy way out though, by generalizing an already existing permission plugin system that so far is only provided on Apple platforms. A patch to Qt enabling this on Unix systems as well is in review currently. With that applied implementing support for requesting location permissions is then very similar to what the positioning plugin already does, you’ll find the code here.

A very convenient side-effect of having permission plugins is that we can now also build a “simulator” that allows testing permission flows in applications while running in an unrestricted development environment and without having to mess with system permission settings each time.

So I did that here, usage is pretty simple:

$ qpermission-simulator [--ask|--grant|--deny] <application-to-test>

Note that this also needs the above mentioned Qt patch to actually do anything, and it currently requires the tested application to be a QApplication in order to show its UI. It does work for all permission types supported by Qt though, not just the location one.

Other positioning sources

One unique feature that microG offers on Google-free Android is using onboard APIs of planes/trains/buses as a location source. That’s useful as the GNSS antennas of those vehicles tend to give you much better results than the one on your phone inside the metal casing of the vehicle.

Of course we have to have that as well, and it’s easy enough to build that since we have an existing library for dealing with onboard APIs already as part of KPublicTransport.

Putting that together with the NMEA 0183 server we get a small KDED module that watches for changes to the Wi-Fi network you are connected to, and if it’s one of a known onboard API it’ll offer its service to Geoclue. As Geoclue will only connect to it on demand (ie. when an application actually asks for a location) it will only poll the onboard API when necessary, so we also get practically no overhead in the idle state here.

Other sources are possible in a similar way as well, e.g. having KDE Connect provide location data from your phone to your desktop computer.

Feedback

This is mostly the result of about two weeks of prototyping, and I’d very much appreciate review and feedback on this. Does the general approach make sense? Is there something else missing around the the location/position topic? Where should the various components live and be distributed eventually (some of this only really relevant inside a Flatpak sandbox fox example)?

Welcome to a new issue of This Week in Plasma!

This week members of the core Plasma team spent almost all of their time in bug-fixing mode! As usual, people unleashed their real-world setups on the new Plasma release and found some issues we missed during the development process, and that nobody reported during the two beta releases. So we made it a priority to fix those issues!

Plasma 6.7.1 was released earlier this week with the first round of fixes, and 6.7.2 is scheduled for early next week with more.

A few new features and UI improvements started landing, too.

Check it out here:

Notable new features

Plasma 6.8

You can now set up wallpaper slideshows that don’t change automatically. Instead you can manually switch the wallpaper via the item in the desktop context menu or its global keyboard shortcut. (Fushan Wen, KDE Bugzilla #518669)

Added an Esperanto keyboard layout to Plasma’s virtual keyboard. (Daniel O’Neill, plasma-keyboard MR #148)

Notable UI improvements

Plasma 6.7.2

Improved text alignment in System Monitor’s Processes page while using the tree view. (Arjen Hiemstra, KDE Bugzilla #442095)

Plasma 6.8

Reduced the number of visual frames in the Menu Editor app. (Levi Leal, kmenuedit MR #59)

Notable bug fixes

Plasma 6.6.6

Fixed an issue that could make KWin crash when some apps opened dialogs and popups in non-standard ways. (Vlad Zahorodnii, kwin MR #9444)

Fixed a regression introduced by Qt 6.11 that made the word “Undefined” appear next to Places entries in the Kickoff Application Launcher widget. (Christoph Wolk, KDE Bugzilla #521799)

Fixed a visual glitch affecting users of Deskflow that could make a clone of the pointer inappropriately remain visible on the client machine. (David Redondo, KDE Bugzilla #521486)

Plasma 6.7.1

Fixed a somewhat common case where KWin could crash on the lock screen when using an NVIDIA GPU. (Xaver Hugl, KDE Bugzilla #520842)

Fixed a recent regression that made KWin crash when using a DisplayLink monitor. (Xaver Hugl, KDE Bugzilla #520361)

Fixed an issue that could make screens plugged into a laptop with both an NVIDIA and an AMD GPU freeze. (Xaver Hugl and SungHwan Jung, KDE Bugzilla #521727)

Fixed a recent regression that broke certain shader-based KWin effects, including the popular “Burn My Windows” effects. (Xaver Hugl, KDE Bugzilla #521774)

Fixed a recent regression that broke color-related KWin effects like color blindness correction and screen color inversion. (Xaver Hugl, KDE Bugzilla #521737)

Plasma 6.7.2

Fixed the currently most common KWin crash, related to variable refresh rates with multi-monitor setups. (Vlad Zahorodnii, KDE Bugzilla #521909)

Fixed a case where Info Center could crash when trying to display information about certain NVIDIA GPUs. (Harald Sitter, KDE Bugzilla #521295)

Fixed a recent regression that broke the RDP server when run using systemd. Sorry about that! (David Edmundson, KDE Bugzilla #521776)

Fixed a recent regression that could sometimes make Chromium-based apps freeze if another window was forced into “Keep Above Others” mode. (Xaver Hugl, KDE Bugzilla #521687)

Plasma 6.8

Fixed a case where Plasma could crash after you ejected an audio CD from Dolphin or Audex. (Kai Uwe Broulik, KDE Bugzilla #522051)

Flatpak 1.18.1

Fixed an issue that made a background service for Flatpak crash if you used the KDE desktop portal dialog to allow an app to update itself while the app was still running. (Sebastian Wick, flatpak issue #6686)

GTK 4.23.2

Made the process of selecting text to later paste it by middle-clicking more reliable in GTK 4 apps. (Vlad Zahorodnii, gtk MR #10006)

Notable in performance & technical

Plasma 6.7.2

Improved full-screen video playback performance in Chromium-based apps. (Xaver Hugl, KDE Bugzilla #521960)

Plasma 6.8

Turned on triple buffering by default for NVIDIA GPUs, because the bugs blocking this from working properly in the past have since been fixed. (Xaver Hugl, kwin MR #9472)

How you can help

KDE has become important in the world, and your time and contributions have helped us get there. As we grow, we need your support to keep KDE sustainable.

Would you like to help put together this weekly report? Introduce yourself in the Matrix room and join the team!

Beyond that, you can help KDE by directly getting involved in any other projects. Donating time is actually more impactful than donating money. Each contributor makes a huge difference in KDE — you are not a number or a cog in a machine! You don’t have to be a programmer, either; many other opportunities exist.

You can also help out by making a donation! This helps cover operational costs, salaries, travel expenses for contributors, and in general just keeps KDE bringing Free Software to the world.

Friday, 26 June 2026

If you've been around KDE, you've probably heard of Techpaladin Software

We're a consultancy that works almost exclusively on KDE, improving KDE upstream while delivering the features and functionality our clients need.

We're growing and looking for more developers to join the team. We're after experienced developers who are already familiar with KDE, C++, and Qt.

We currently have two positions available:

  • Someone with a keen eye for design to work on high-level features and help shape the user experience.
  • Someone with a more technical background to work on lower-level system integration and platform work.

In return, you'll get to work with some of the most talented and welcoming developers in this space... and also me!

If that sounds interesting, you can find more information and apply here:
https://techpaladinsoftware.com/joinus.html

KDE Eco organized a two-day sprint to work on KEcoLab — the energy measurement lab I maintain. A few more people came and joined on day two, which made the discussions richer. The sprint was mostly about figuring out the next steps for KEcoLab, fixing some open issues with the measurement pipeline, and trying to get a second system set up in the lab. You can find the full sprint notes here.

Thanks to KDE e.V. for sponsoring the sprint, KDAB for hosting us at their Berlin office, and Volker for the guidance and support throughout.

Headless Remote Access

The first thing we wanted to sort out was making the lab PC fully remotely accessible, which means we could use it without having someone physically in the room to debug our issues with the lab PC. SSH was already working fine, but RDP was not very reliable (it used to break sometimes). Nowadays, We had to go to the lab PC in person once to allow remote connections, which is exactly the kind of thing you do not want to do repeatedly. During the sprint, we applied a fix using flatpak permission-set to persist screen capture permissions across reboots, based on a recently merged patch (plasma/xdg-desktop-portal-kde!326).

However, the issue is not fully closed. A couple of days after the sprint, the problem came back and it was not clear what had changed. We had a follow-up meeting to discuss this, notes here. Joseph and Volker are currently testing different approaches to figure out how to properly persist the session across reboots. We will update this once we have a reliable fix.

Setting Up a Second Machine

Cornelius Schumacher donated a Fujitsu Esprimo 510 to the lab for us to add as a second System Under Test. It did not go well. The machine threw six beeps on boot, which pointed to a CPU or motherboard problem, most likely a BIOS flash failure. We tried reseating the RAM, resetting the CMOS battery, testing each RAM stick one by one. Nothing changed. The machine is not usable, but we are keeping the hardware for spare parts.

Debugging the Okular Pipeline

We ran the full Okular measurement pipeline on Wayland and hit a few problems. On day two, we saw an R error about non-numeric data. When we looked into it, the collectl files had data from pipeline runs we had stopped earlier, stopping a pipeline mid-run was causing the next run to append data to existing files, which broke the statistical analysis. We now have issues open to fix this properly:

  • Kill pipeline: #64
  • Failsafe for pipeline failure: #18
  • Cancel SUS script: #16

A cleanup stage has since been added to the pipeline to handle this — see !152.

The reports also had wrong durations and missing averages. That turned out to be missing stopActions in the ydotool scripts. Once we fixed those, the numbers looked reasonable. Joseph is continuing to work on this and will follow up on the remaining open questions.

There is also a broader question about the data itself. Our power draw results look very different from measurements taken at Umwelt Campus Birkenfeld back in 2022. Their data showed distinct power draw phases across tasks, while ours is mostly flat apart from the spike when Okular opens. It could be Wayland versus X11, Flatpak versus a repo package, or just Fedora versus Ubuntu. Probably a mix of all of them. Something to investigate.

Future Planning

We went through the open issues and talked about what comes next, integrating KEcoLab into a broader KDE Plasma testing workflow, planning for the Akademy BoF, and ideas around extending ydotool/kdotool to make measurement scripts more flexible. We did not get through everything but the direction is clearer now.

Outside the Lab

After the first day, Carl, Aakarsh, Joseph, and I headed to Tempelhofer Feld. It was a warm evening and the field was full of people cycling, skating, and just sitting around. We walked around for a while and talked about everything except KEcoLab, which was exactly what we needed. A big thank you to Carl and Joseph for showing us around, Berlin has a way of making you feel like you have all the time in the world, even when you have a pipeline to fix in the morning.


Not everything worked, but we came away knowing exactly what needs to be fixed and why. That is usually what a good sprint looks like.

Tempelhofer Feld

Tempelhofer Feld

Wednesday, 24 June 2026

Or at least that was the plan...

The original intent was simply to fix an issue in the Oxygen cursor theme. Some cursor sizes were missing and i thought this would be one of those quick fixes. You know... the kind that takes 10 minutes. Several days later I was redoing most of the animated cursors.

One of the things I care a lot about is how much movement contributes to personality. Not just in interfaces, but in general. Animation is a bit like music. Two notes can contain the same information and still communicate completely different emotions. A lot of modern interfaces IMO tend to treat animation as "decoration". I tend to believe that movement is communication. The way something moves tells you what it is, and if not, at least makes it interesting to look at. I think it also comes across to users that if an animation has personality, then the developer or designer actually cares about the experience.

One of the things that fascinates me about animation is that humans are absurdly good at detecting natural motion. We can forgive low resolution graphics, simplistic shapes and even questionable artwork. But if movement feels wrong people notice, even if they dont know why.

Anyway, while revisiting the Oxygen cursors I wanted to stay close to what Ruphy originally created all those years ago while making them a bit more expressive. The busy animation is probably the best example. The old animation revolved around circular motion and the new one still does, but now its inspired by one of those old physics toys with pendulums and metal balls transferring momentum from one side to the other. Tension, release, acceleration, deceleration... tiny little things most people will never consciously notice, but i think they feal them.

What started as fixing a few missing cursor sizes somehow ended with redoing most of the animations. Classic scope creep. The good kind :).
side note i still managed to not fully fix the original bug i was trying to fix... but you can try it here

The new Oxygen cursors, together with all the other improvements we've been making over the last few weeks, should be arriving with KDE Plasma 6.8. There is also a ton more that I'll mention in another blog post soon, and that Filip already hinted at in his own post.

In the meantime 6.7 is out, and I hope you are enjoying what we have done so far. Its been fun seeing this old project slowly finding its place again, and I hope you'll have as much fun using it as we've had bringing it back to life.

This year, there was another display next hackfest, this time in Nice, France. This was a very productive hackfest, so I’ll focus just on my personal highlights here.

KMS backlight property

As mentioned in the blog post about the last hackfest, the current backlight API on Linux is a total mess. To remind you, the kernel exposes backlight devices through sysfs, which has several problems:

  • this API doesn’t tell you which display the backlight is for. Effectively, only one backlight is supported
  • some of the backlight devices don’t actually work, it’s up to userspace to figure out which one to use
  • you need root privileges to change the backlight brightness
  • there’s no proper minimum. On some displays, backlight level zero turns the backlight off, on others that’s the minimum brightness. In some cases, non-zero but very low levels result in wrong colors
  • there’s no information on how long it takes to apply brightness changes

The new KMS API adds a backlight property to connectors of built-in panels (external monitors may be supported later), so the compositor knows exactly which display it’s for, and it can change the backlight without needing more permissions than it already has for driving the display.

We talked about the requirements to merge the API, concluded that it’s okay to leave it at one unit-less value for now (it can be trivially extended later), wrote and tested implementations and it’s pretty much ready to be merged.

KMS colorops

KMS colorops allow the compositor to offload some color operations to the scanout hardware, which can save a lot of power. We discussed how to best extend it to support YCbCr buffers, which are required for efficient video playback, and tested an implementation of the addition in amdgpu.

The implementation had some bugs with interesting visual results, but we debugged that and could find the source of the problem. The API for this should be merged sooner than later as well.

Scheduling Atomic Commits

As another follow-up to last year’s hackfest, we now had an implementation for what we agreed on last year:

  • a callback that gives us a timestamp for when the hardware finished programming the last commit
  • information on when the deadline is, relative to the start of vblank

We also talked about how all of this should work with ultra high refresh rate monitors, since CPU schedulers are quite bad at timing things precisely. To put things into perspective: KWin currently sets the target commit time to 1ms before vblank, since schedulers sometimes wake up KWin’s thread hundreds of microseconds later than planned.

With a 1000Hz display, the compositor would only have 1ms to commit each frame, so that doesn’t exactly work out well. Worst case, the compositor may need to immediately commit the next frame once the last one is finished, but in an ideal world, the kernel would ‘just’ be able to schedule the compositor’s threads more accurately.

VRR and QMS

Variable refresh rate has a few annoying problems right now:

  • when the refresh rate changes too quickly, many displays change in brightness, which is visible as flickering
  • HDMI doesn’t require displays to make switching between VRR on and off seamless, so many TVs go blank for a second when doing this
  • compositors currently don’t have any (good) way to set an exact refresh rate without turning VRR off

All of these issues can be solved by allowing the compositor to set a minimum and maximum refresh rate that the display needs to stay between. We had two proposals for this:

  1. allow compositors to set a minimum and maximum refresh duration in nanoseconds
  2. allow compositors to set a minimum and maximum refresh rate with a numerator and denominator for both rates

For compositors, the first one is generally simpler, but the second one is needed for HDMI’s QMS feature. The “Quick Media Switching” functionality makes TVs switch to exact video refresh rates, which are specified as a numerator and denominator rather than a duration.

We still need more implementations for this to move ahead, but the direction to go in seemed pretty clear.

Color formats and BPC

Currently on Linux, if you want to configure how the image is sent to your display, you’re out of luck. Both the bit depth (how many bits per color are used) and the color format (RGB vs. YCbCr, chroma subsampling) can’t be configured, the driver chooses both automatically.

The new color format KMS property will solve this problem for the color format side, and we discussed how to do the same for bit depth. We concluded that a “min bpc” to match the already existing “max bpc” would likely be the best way to do this, since compositors can either choose a specific bpc that way, or leave it up to the driver to pick the best possible value.

FreeSync HDR, HDR10+, HDMI SBTM

Anyone that’s used HDR for some time knows that displays basically never do it right. Their tonemapping behavior can be unpredictable, and especially TVs often do a lot of “interesting” things in an attempt to improve the image, which can have very bad effects on PCs and video games.

For example, my TV by default makes images brighter than they are. If I use the brightness slider in Plasma, the TV literally compensates the reduced brightness away!

FreeSync HDR is one way to solve this problem: Instead of sending a signal to the screen that’s way larger than required (BT.2020 + PQ), just give the display an image in its native colorspace (native primaries + gamma 2.2 with 1.0 being the maximum luminance), and ensure it does the absolute minimum amount of tonemapping possible.

While TVs sadly don’t usually support this mode, a lot of higher end gaming monitors do, and as it turns out, supporting it on Linux wasn’t actually all that difficult - I already have a kernel patchset to enable the functionality that happened to be mostly there in amdgpu already, and on the compositor side it was entirely trivial. The only part that’s still missing is parsing the relevant bits from the monitor’s EDID to figure out if it actually supports that mode.

Specifications for the FreeSync information in the EDID are unfortunately not public (yet?), so we’ll have to reverse-engineer it. Luckily, some people have already gotten most of the way there, we just need to implement it in libdisplay-info and verify its correctness with a bunch of screens.

HDR10+ and HDMI Source-Based Tone Mapping are other standards intended to solve similar problems, and we’d really like drivers to implement them as well.

Atomic commit feedback

There was some discussion on how compositors can get feedback on why a particular atomic commit failed. There are two big cases where this is important:

  • when trying to change the display configuration, especially enabling displays for the first time
  • when trying to find the optimal setup for overlay planes1

Currently, graphics drivers effectively just say “no” when something doesn’t work, and both compositors and users are left to try random things until hopefully some configuration is usable.

There’s an existing patchset to provide such information, which is very useful for display configuration, but less useful for overlay planes. We talked a bit about how this could possibly be improved, how the API might be extended in the future, and whether or not a userspace library that’s more aware of vendor-specific hardware (and driver) limitations might be a better approach for improving overlay plane usage.

linux-dmabuf version 6

This latest version of the linux-dmabuf protocol allows the compositor to advertise that it supports multiple GPUs, and allows applications to set which GPUs they’re using. I’ll make a separate blog post about this, but the important bit is that it allows for performance improvements in many systems with multiple graphics cards. This is quite the extreme case, but on my setup with an external GPU, using this protocol in Mesa and KWin literally improves performance in Cyberpunk 2077 by 100%!

After some explanation of how it works and minor adjustments to the protocol text, we merged it. There’s even a wayland-protocol release for it now!

Non-blocking modeset commits

The KMS API has some annoying quirks, and one of them is how you request an event for images being presented. You can request these page-flip events with a flag on each atomic commit, but if you try to present to multiple CRTCs (usually one per screen) at the same time, you get one event per CRTC.

That part by itself is fine, but what’s more problematic is that the kernel has a pretty old workaround for some old and buggy compositor: It doesn’t allow you to request page-flip events if any of the CRTCs in an atomic commit are actually turned off.

Because of this, for changing the display configuration, KWin currently uses a blocking commit, which can take up to 90ms in my testing (with a single screen) and blocks KWin’s main thread for that time. At the hackfest, Simon put together a kernel patch for allowing compositors to request a page-flip event per CRTC instead of globally, which solves this problem very nicely.

Switching between compositors

When you switch between compositors, currently the compositor you switch to gets all the KMS state from the compositor you switched away from. This can be very convenient for smooth transitions, for example when logging in from the Plasma login manager to the Plasma Wayland session, but it can also go wrong, for example when logging in from the Plasma login manager with HDR enabled into an Xorg session that doesn’t understand HDR at all.

This problem has existed since the day KMS was created, and there was never a good solution for it. Some compositors “clean up” after themselves before you switch virtual terminals, but that workaround prevents those smooth transitions and it’s not a fully robust way of fixing this.

We looked into finally fixing this properly, and concluded that we want a flag in an atomic commit that makes the kernel reset everything to some sane default state before applying it. This way, we can get more reliable switching between compositors without having to compromise on smooth transitions where possible.

Driver bugs

When doing bug triage for KWin, I usually spend a significant amount of time telling our users that their problems are caused by bugs in graphics drivers and where to report them. So I’m especially happy to hear about important problems being solved:

  • the likely by far biggest source of page-flip timeouts on AMD GPUs is finally getting fixed. This was especially bad on AMD laptops, where leaving PSR2 enabled could trigger such a freeze multiple times each week
  • a Nvidia driver bug causing freezes when using overlay planes is getting fixed
  • slow atomic commits on AMD are getting improved. I wrote a KWin autotest that consistently triggers the issue at the hackfest, and Harry made a fix for the most severe cases since then. On my laptop the stutter caused by it isn’t usually noticeable, but on dedicated GPUs it was pretty bad

More than just being very annoying, these specific issues are also the blockers for enabling overlay planes by default in KWin on the respective hardware. I have high hopes that we can finally enable overlay planes by default on all hardware this year!

Conclusion

I’m really glad to see so much progress on these topics. My nearly infinite wishlist for driver changes is actually shrinking for once!

Thank you to Collabora for organizing and sponsoring the event, and thanks to all the awesome people for being there and making things happen :)

group picture


  1. see my earlier post about overlay plane usage 

  2. PSR stands for “panel self-refresh” and can save a decent amount of power while the screen isn’t changing 

For those who are not yet familiar with the new Qt Canvas Painter, please check the previous blog posts: Introduction, new features, and performance measurements. This blog post introduces paths and path groups to further improve the performance.

Tuesday, 23 June 2026

Just something I experience more and more these days.

When it comes to reviewing code, the descriptions, commits and such can be massive blast of information: Full of extraneous details depicting what was changed. The main point is why was something changed. And often in only one huge commit with massive diffs.

I'm sorry but my poor ADHD brain can't take this very well. I don't want to read a novel. Usually blurbs of text are fine: Extraneous detail I can ask about if I need to know.

So this is my plea, from accessibility-ish(?) standpoint, to keep commit messages, merge request descriptions and code comments clear, to the point, need-to-know basis. Do not explain what, but why. Usually the code itself is enough to tell rest of the story. If not, I will ask questions. That's why it's a review.

It's easy to think that having huge description with all and everything is the way to go, but it will just make it slower for people like me to review it. I can barely concentrate already..

Then commits should always be atomic, especially during merge review. Use git amend to make small changes. Before merging, rebase and clean up, or squash. But try your best keep commits atomic: changes that can stand alone.

(Note that this is not aimed at any specific individual, I just finally had brains to write this post since I was reminded of the topic.)

If you use LLM tools, please still write comments, descriptions, commit messages etc. yourself. It helps you to understand whats going on, and it's more accessible for me to review. (Or better yet, try to avoid these tools if you can. I don't think anyone actually needs them. You're good enough without, I promise!)

edit: Seems people are upset about me mentioning accessiblity there. I do not know what is the best way to describe it. But you can just ignore this blog post if it annoys you.

Monday, 22 June 2026

Hey wassup guys! Welcome to yet another blog made by me!

I've been busy for a while due to exam stress and my passport situation.
But I am glad to share that I finally got the passport yesterday! This brings me one step closer to making it to Akademy 2026 in Graz, Austria.

Now I just need to get my flight and hotel bookings done, get some required documents signed from my university, get a VISA or a forex card and then finally apply for the Austrian Schengen VISA.

Anyways, this blog is supposed to be about sharing learnings / progress made in week 2 and 3 of my GSoC journey so let's go!

If I recall correctly, I did the following in the past 2 weeks:

Work on some CI issues in the android image and the windows MinGW image.

  • I had to build harfbuzz from scratch for the android image because it simply didn't have it by default.
  • For the windows image, I actually found a bug in harfbuzz which made the windows build fail. I filed an issue and they fixed it very quickly by using AI https://github.com/harfbuzz/harfbuzz/issues/6026. I don't really like it myself that harfbuzz is heavily using AI in its development but I think I can't really do much about it. Perhaps this is a topic worth covering in another blog?

Destroying resources after we have no use for them.

  • I was leaking some memory by using harfbuzz to generate subset fonts but was never really calling the destroy functions required to free that memory.

Fix a dangling pointer bug that caused invalid fonts on subsetting.

  • I unknowingly made a serious dangling pointer or use after free bug when I was working on destroying harfbuzz resources after I had used them. The gist here was that I used a class called MemStream but didn't realize that it actually had a read-only view on my subset font data, let's say const char* fontData. I called harfbuzz destroy function after constructing this stream and it freed the fontData and then when the time came for writing to the file, the fontData pointer inside the stream was dangling and corrupted data got written.

Making font subsetting an optional feature

  • I reported the harfbuzz issue and the patch MR got merged so does that mean the windows CI would also get fixed immediately? Not quite, the harfbuzz people would first need to release a release and then it needs to be updated in the package repository to finally get the patch working. We aren't sure about just how much time this is going to take so I worked on making the font subsetting functionality optional by using CMake options magic.

What I learned

  • I am now less likely to make dangling pointer mistakes but it could still happen.
  • Quite a lot of CMake and how to do optional features with it.
  • Dealing with CI.
  • And a couple more things I forgot about but I did actually learn from them.

Conclusion

I think I did like below-okayish amount of work done but I am glad I actually learnt a lot of useful and important things.

I would like to thank my mentor Albert Astals Cid, and the Poppler community for helping me. I would also like to thank KDE board members for approving my reimbursement requests.

And finally, thank you for reading my blog so far :)

Until next time!

So, last road map discussion it was decided I would start working on HDR. This is partially because I have the hardware for it, as well as Krita now supporting the wayland color management protocol, so my hardware is actually being used appropriately.

Furthermore, before I worked on text my specialization within Krita is its color management code, so I feel a little like a fish in water right now.

HDR tends to mean three separate things:

There’s the hardware side, where a screen can show such bright colors that it needs to be interacted with in a special way to make good use of those colors. This particular manner also informs how we store HDR values inside file formats.

There’s the scene referred workflow, where we assume there’s a scene white, usually the brightness of a diffuse white, like paper, and highlights are above that are the high dynamic range.

Finally, there’s the tone mapped result of a scene referred image. That means that we take the scene referred image, and scale everything so that the result fits into a regular SDR range. This is typically the version that people learn of first when they scroll photography websites.

For Krita’s purpose, we’re largely interested in the first two. The hardware and file format side in particular needs a lot of work to get all the metadata right. For the scene referred section, the filters need adaptation. But the last entry is necessary to create a nice result image for social media, so I’ll cover that in the future too.

For now, I focused on getting some UI fixes in.

Canvas Decorations

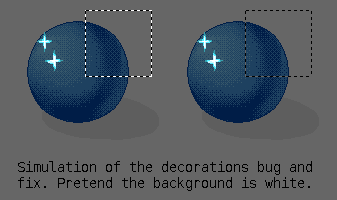
So, the first thing that needed tackling was the user interface. In particular, when using previous versions of Krita, the canvas decorations were blown out.

Basically, this happened because we draw our decorations onto the OpenGL canvas with a QPainter. Because QPainter nor QColor has any concept of what space it is drawing in, it doesn’t know to convert from sRGB to the rec2100pq format we’re using for the HDR canvas. We also have the issue that sometimes, colors aren’t in sRGB, but rather should represent a color from the image. Previously, we could assume that if the display was wide gamut, we didn’t need to adapt the decorations, or treat them differently from image colors, so we just treated them as the same thing, and drew the colors straight onto the display color space.

Now, the only place that knows how to handle image colors properly, applying all the OCIO config, etc, as well as having information to convert sRGB to the canvas space is the display color converter inside the canvas. This one has an extra simplified interface, called the color display renderer. Most of the work to fix this was to add functions to this renderer interface to convert colors (and images) and finally funnel the renderer through all canvas decorations. This was about 130 changes in the end.

Most of them were just plain conversions from sRGB to canvas space, but the color picker had to use the actual image color, as did the preview for the transform tool. Nor everything had to be converted on the fly. In some cases, like the vector tools, we have a set of colors we reuse, so those were added to the display renderer to be converted as a single struct of colors. Then, there’s the on canvas toolbars, like for the selection tools. These just use QPalette colors, which was solved in a similar manner, with the display renderer keeping a version of the current palette, but converted to the canvas space. At some point, we might need to do the same with KColorScheme, except that this class doesn’t have a way to change colors inside of it. Not sure what the best solution here is, as Krita needs to control the conversion function (in case of wide-gamut, etc).

Then, there were the reference images. Reference images are drawn on the side of the canvas in Krita. While fixing them was easy enough, I went a little further: Enabling HDR and wide gamut on the reference images. This was a little bit ambitious, as it required converting between QColorSpace and our similar class, KoColorProfile (a KoColorSpace, if you’re curious, is a KoColorProfile and a bit depth, as KoColorSpace has a whole bunch of per-model+bit-depth functions to wrangle pixels).

This conversion isn’t too hard, because QColorSpace can read and return iccprofiles, and KoColorProfile can do the same. However, for rec2100pq in particular, we will want to return a profile of our own. Same with sRGB. So what happens before we try to load the icc profile is that we test the transfer and the like, and funnel the values into our profile searching system. This system was created to handle ITU CICP values (basically a standardized set of enums for transfers and colorants), and was already extended with the known quantities outside of that (Adobe RGB, ProPhoto), so it can handle all the predefined transfers and colorants QColorSpace supports and find the relevant profile before trying to create it.

Now, when we load a reference image, and the image is RGB, Krita will convert it to a QImage, but set the colorspace to use that RGB space. The exception is when the image is floating point, in which case it’ll be converted to rec2100pq, because our reference images are eventually stored as PNG, and PNG cannot handle floating point. Then, when we start drawing the reference images, we first ensure the QImage QPaintDevice has its QColorSpace set to use the canvas colorspace. When drawing, we test the color space of the device, and the colorspace of the reference image, and then do the conversion to the canvas space before drawing.

And it works. I’m pretty pleased with this, because we have a bunch of other places we still draw with QPainter that might be useful to color manage, with the most notable one being the vector shapes. I hope we’ll be able to tackle that in the near future.

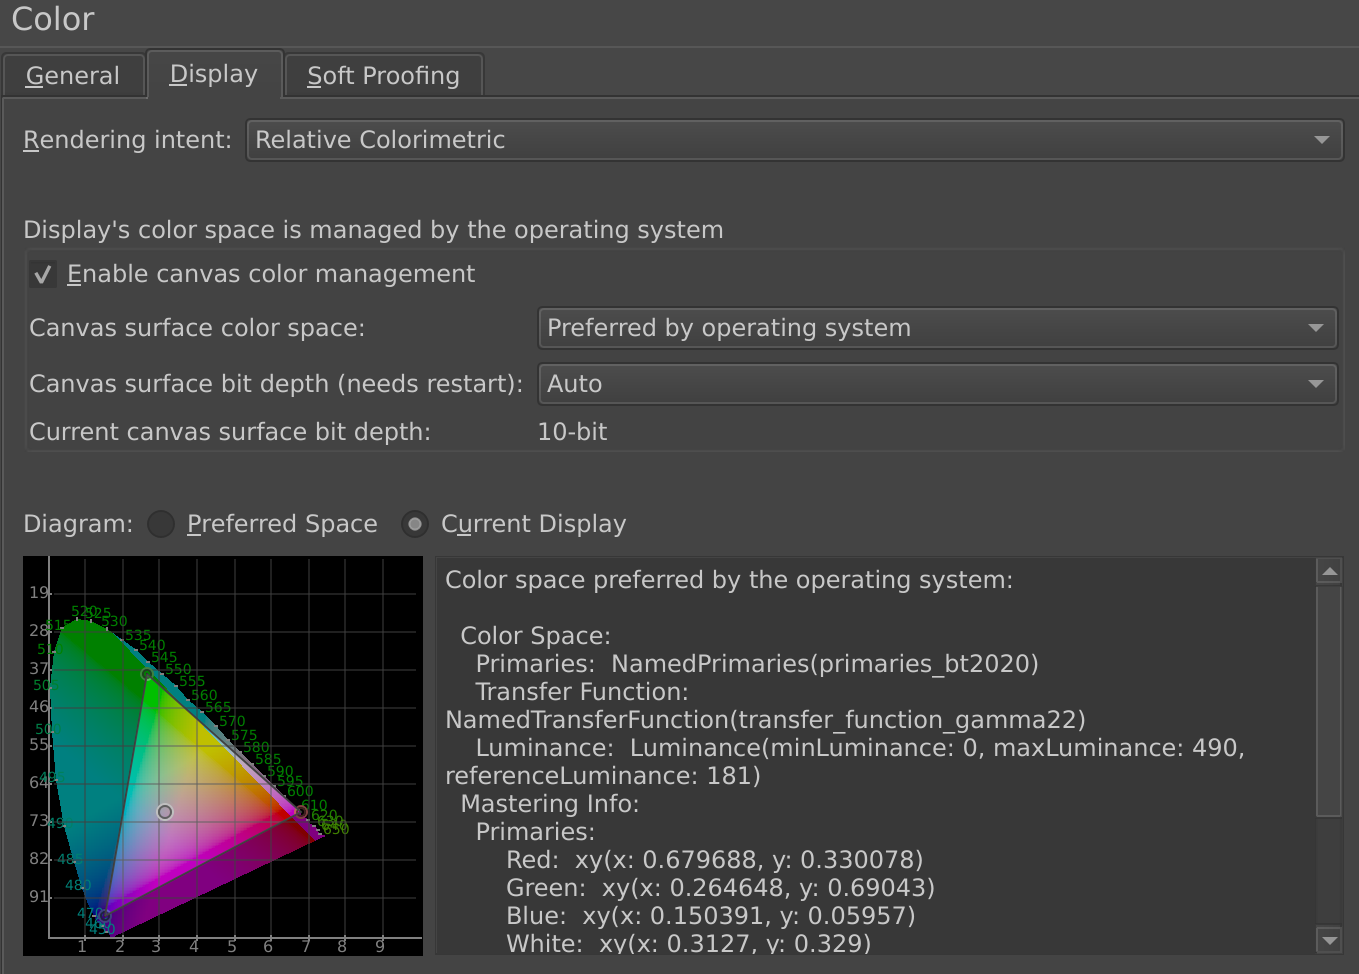
Improving the color management page

This was basically setting a little widget to show the color space data we get from wayland. Wayland sends us two types of information: The preferred color space, and the mastering display data. The former is the space wayland suggests that we send data in for the least amount of color conversions. The second is a little bit more weird. The mastering display color volume in HDR terms is a bit of metadata to indicate the gamut of the display that the image was finalized on. The idea being that this info can help guide the gamut mapping process by indicating in what range the important contrasts are.

In practice, what wayland is sending here is the color volume of the display the current window is on. I think this is so that we can send that data right back when we’re sending HDR data for the image that is being authored on that display.

The CIE tongue widget now can switch between the preferred space and show the display of the current color space. In this case, it’s showing that my screen is a p3-like, as many HDR screens are.

So, I made the XY CIE Tongue widget display these spaces with a toggle to switch between the preferred and current display gamut, and an auto update when the preferences switches screens. It might seem small, but one of the reasons I ported the CIE tongue widget over from Digikam all those years ago is because I do feel it is much more friendly to be able to see the actual gamut instead of having to interpret magic numbers and names.

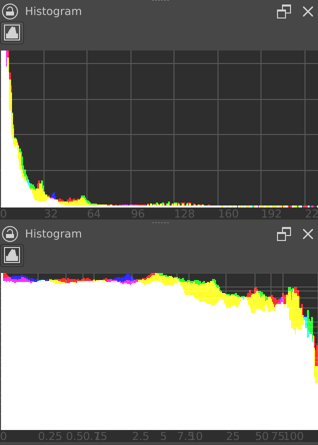
Making the Histogram handle floating point

Our histogram docker was limited to [0 1], which isn’t very useful when working in linear floating point, so I wanted to fix that. So, a histogram in Krita is made by taking a vector of integers, initializing that with 256 values, and then going over each color and incrementing the value that is associated with the value of the pixel. You then do this per-component, to get a view of where the pixel values are per-channel.

What needed to be added here was that we now first test all the pixels for the maximum possible component value. Then, afterwards we divide the range of 0 to maximum by 256, and use that to sort the pixel values into. This means that as the image gets a bigger range, the precision of the histogram decreases, but as far as I know its output should still be statistically relevant.

Two screenshots of the histogram docker for the openExr sample image “desk.exr”. The top is without logarithmic scaling. The numbers at the bottom indicate that the image goes well beyond 200.0 in value (where 1.0 is diffuse white). At the bottom, the logarithmic scale works both in the x and y axis, showing the spread of values more clearly.

Of course, in really wide range images, the range becomes a little meaningless. Therefore, it was decided to add a toggle to switch into logarithmic mode as well. For this, to keep the precision sensible, it needs to sample a separate logarithmic vector during pixel sampling. This has the added benefit that switching between linear and logarithmic is instantaneous.

Then I spend some time tweaking the graph and adding numbers at the bottom.

One thing I’m a little worried about though: The log grid is using log10. But with HDR there’s a concept of stops, which is log2. And I’m wondering if I should switch the logarithmic mode to log2 instead of log10, but at the same time, I’ve never seen log2 graph paper.

Vector Cursors

This has nothing to do with HDR, but I also converted all the cursors to SVG. This was something I did when there was a lull in the text work last year, because my screen is also a high dpi screen, and the cursors in X11 were tiny. So, I spend some time redrawing all the cursors, and then load them with QIcon(file.svg).toPixmap(width, height) to get a display scaled pixmap to use with QCursor. Of course, this then got delayed because there were issues with hot-spot offset and Android, and then I had to return to the text work. I managed to get back to this recently and finalize it.

I’m kinda happy, because between the vector cursors, the color managed canvas decorations and the fact canvas decorations get scaled (something I did… two, three years ago), everything we can draw on the canvas now looks good on modern displays.


Next up is going to be digging into the weeds of HDR metadata.