Skip to content

Friday, 13 February 2026

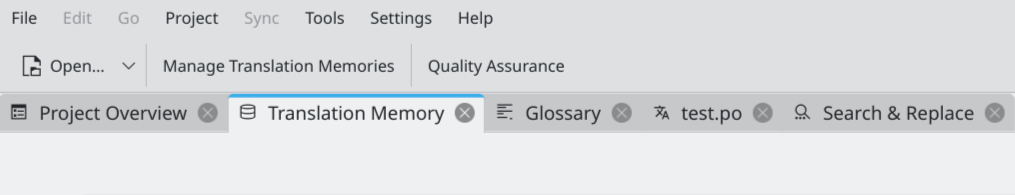
Going into Week 3, my next task was clear. I had successfully stopped the Lokalize menubar from jumping around, but it left me with top-level menus that were clickable but completely empty depending on which tab you were using. My goal was to figure out how to dynamically grey out those useless menu headers, like the "Sync" menu in the Project Overview, so users wouldn't be tricked into clicking them.

I started by checking the Qt documentation and a very helpful discussion on the Qt forums to see how to properly handle this. The forum thread highlighted a crucial distinction in the Qt API: using setVisible(false) completely hides a menu, while setEnabled(false) keeps it visible but greys it out. This was an important detail. If i had used setVisible(), the menus would have vanished completely, bringing back the jumping ui bug I had just fixed in Week 1. I needed to use setEnabled() to keep the menu structure frozen in place while making the empty headers unclickable.

To implement this, I hooked directly into the application's tab-switching logic. I wrote a new function that gets triggered every single time a user changes tabs. It grabs the main menubar and loops through every top-level action. For each menu it finds, it checks if the menu has any currently visible actions. If the answer is no, it disables that specific menu header using action->setEnabled(false), turning the menu grey so the user knows it cannot be clicked.

void LokalizeMainWindow::updateMenuAvailability()
{
    QMenuBar *bar = menuBar();
    if (!bar)
        return;

    // Refresh top-level menu state based on currently available actions.
    for (QAction *action : bar->actions()) {
        QMenu *menu = action->menu();
        if (!menu)
            continue;

        // Disable top-level menu when it has no visible actions.
        action->setEnabled(menuHasVisibleAction(menu));
    }
}

bool LokalizeMainWindow::menuHasVisibleAction(const QMenu *menu) const
{
    for (QAction *action : menu->actions()) {
        if (action->isSeparator() || !action->isVisible())
            continue;

        if (QMenu *subMenu = action->menu()) {
            // Check submenu actions too.
            if (menuHasVisibleAction(subMenu))
                return true;
            continue;
        }
        return true;
    }
    return false;
}

The tricky part was writing the helper function to accurately figure out if a menu was actually "empty." It wasn't enough to just check if the menu contained items. Inside the helper, I loop through the menu's actions. If an item is just a ui line (a separator) or is already hidden, the code skips it. I also had to account for nested submenus, so if the action is a submenu, the function calls itself recursively to check inside it. The implementation is completely generic-meaning if anyone adds new menus or actions to Lokalize in the future, this code will handle them automatically.

After the fix: In the Translation Memory tab, the Edit, Go, and Sync menus dynamically grey out. This adapts instantly to whichever tab is active (for example, switching to the Project Overview will only grey out the Sync menu)

I opened the merge request, and i'm happy to say it was quickly merged into master! The Lokalize menus now update smoothly based on the context of the active tab. They stay exactly where they belong, and empty menus disable themselves as expected. With this menubar issue resolved:)

Thursday, 12 February 2026

As explained in one of my previous blog posts where I revamped the unresponsive window dialog, KWin isn’t really designed to show regular desktop windows of its own. It instead relies on helper programs to display messages. In case of the “no border” hint, it just launched kdialog, a small utility for displaying various message boxes from shell scripts. This however came with a couple of caveats that have all been addressed now:

KWrite (simple text editor) window without window border. Ontop a dialog “You have selected to show a window without its border. Without the border, you will not be able to enable the border again using the mouse: use the window menu instead, using the Alt+F3 keyboard shortcut”, buttons “OK” and “Restore Border”
Setting no border now lets you restore it in case you really don’t have a keyboard

First of all, the dialog wasn’t attached to the window that provoked it. When the window was closed, minimized, or its border manually restored, it remained until manually dismissed. Secondly, it said “KDialog” and used a generic window icon (that would have been an easy fix of course). Further, the user might not even have kdialog installed which actually was the case on KDE Linux until very recently. Ultimately and most importantly, it told you that you were screwed if you didn’t have a keyboard but didn’t offer and help if you really went without one. I therefore added an option to restore the border right from the dialog. Should you have a dedicated global shortcut configured for this action, it will also be mentioned in the dialog.

The dialog when manually setting a window full-screen has similarly been overhauled, including an undo option. While at it, I removed the last remaining code calling kdialog, too: the “Alt+tab switcher is broken” message. It is now a proper KNotification. Something you should never see, of course.

Another dialog that I gave some attention was the prompt when copying a file would overwrite its destination. If you have Kompare installed and copy a plain text file (that includes scripts, source code, and so on), the dialog displays a “Compare Files” button. It already guesstimated whether the files are similar but now you can actually see it for yourself.

Dialog prompt asking “Would you like to overwrite the destination?”, Source (from a ZIP file) and Destination (in Downloads folder) both show a preview image and size and modified time.
Extracting a file from Ark now displays information about the source, too

KIO’s PreviewJob that asynchronously generates a file preview now provides the result of its internal stat call, too. This means that once you receive the preview, you also get the file’s properties, such as size, modified time, and file type basically for free. The rename dialog then displays this information in case it wasn’t provided by the application already. Dolphin now also makes use of this information while browsing a folder which should improve responsiveness when browsing NFS and similarly mounted network shares. At least when previews are enabled, it no longer determines file types synchronously in most scenarios.

Since the rename dialog is able to fetch file information on demand, Ark, KDE’s archiver tool, rewrites the source URL it displays in the dialog to a zip:/ URL (or tar:/ or whatever supported archive type). This way the dialog can display a preview transparently through the Archive KIO worker which also gained the ability to determine a file’s type from its contents. In case you didn’t know, you can configure Dolphin to open archives like regular folders.

Finally, most labels in KIO that show the mtime/ctime/atime no longer include the time zone unless it is different from the system time zone. Showing “Central European Standard Time” in full after every date was a bit silly. Unfortunately, QLocale isn’t very flexible and only knows “short” (19:00) or “long” (19:00:00 Central European Standard Time) formats. You can’t explicitly tell it to generate a time string with seconds, or with 12/24 hour clock, or a date with weekday but no year, and unfortunately the “long” time format includes the full time zone name.

Tuesday, 10 February 2026

Guide: Creating a C++ Extension for Falkon Browser This guide walks through creating a basic “Hello World” plugin in falkon. 1.

Monday, 9 February 2026

In my last post, I laid out the vision for Kapsule—a container-based extensibility layer for KDE Linux built on top of Incus. The pitch was simple: give users real, persistent development environments without compromising the immutable base system. At the time, it was a functional proof of concept living in my personal namespace.

Well, things have moved fast.

rocket launching

It's in KDE Linux now

Kapsule is integrated into KDE Linux. It shipped. People are using it. It hasn't caught fire.

The reception in #kde-linux:kde.org has been generally positive—which, if you've ever shipped anything to a community of Linux enthusiasts, you know is about the best outcome you can hope for. No pitchforks, some genuine excitement, and a few good bug reports. I'll take it.

Special shoutout to @aks:mx.scalie.zone, who has been daily-driving Kapsule and—crucially—hasn't had it blow up in their face. Having a real user exercising the system outside of my own testing has been invaluable.

Bug fixes

Before shipping, I spent a full day rigorously testing every main scenario I could think of—and writing integration tests to back them up. (Those tests run on my own machine for now, since the CI/CD pipelines don't exist yet. More on that below.) The result: the first version that landed in KDE Linux was quite stable. There was only one minor issue that isn't blocking anything.

CI/CD

I'm in the process of building out proper CI/CD pipelines. This is the unglamorous-but-essential work that turns a "project some guy hacked together" into something that can be maintained and contributed to by others. Automated builds, automated tests, the whole deal. Not exciting to talk about, but it's what separates hobby projects from real infrastructure.

Konsole integration

This is the one I'm most excited about. In the last post, I mentioned that Konsole gained container integration via !1171, and that I'd need to wire up an IContainerDetector for Kapsule. That work is underway, with two merge requests up:

!1178 (Phase 2) adds containers directly to the New Tab menu. You can see your available containers right there alongside your regular profiles—pick one, and you get a terminal session inside that container. Simple.

containers in new tab menu

A big chunk of this work was refactoring the container listing to be fully async. There are a lot of cases where listing containers can take a while—distrobox list calls docker ps, which pokes docker.socket, which might be waiting on systemd-networkd-wait-online.target—and we absolutely cannot block the UI thread during all of that.

!1179 (Phase 3) takes it a step further: you can associate a container with a Konsole profile. This is what gets us to the "it just works" experience—configure your default profile to open in your container, and every new terminal is automatically inside it.

container profile configuration

These lay the groundwork for Konsole to be aware of Kapsule containers. The end goal hasn't changed: open a terminal, you're in your container, you don't have to think about it. We're not at the "it just works" stage yet, but the foundation is being poured.

Future work: configurable host integration

switchboard operator

Right now, Kapsule gives you some control over how tightly the container integrates with the host. The --session flag on kap create lets you control whether the host's D-Bus session socket gets mounted into the container. That's a good start, I think I need to go further.

The bigger issue is filesystem mounts. Currently, Kapsule unconditionally mounts / to /.kapsule/host and the user's home directory straight through to /home/user. That means anything running inside the container has full read-write access to your entire home directory.

That's fine when you trust everything you're running, but some tools are less predictable than others. There are horror stories floating around of autonomous coding agents hallucinating paths and rm -rfing directories they had no business touching. Containers are a natural mitigation for this—if something goes sideways, the blast radius is limited to what you explicitly shared. But that only works if you can actually control what gets shared.

The fix is making filesystem mounts configurable. Instead of unconditionally exposing everything, you should be able to say "this container only gets access to ~/src/some-project" and nothing else. Want a fully integrated container that feels like your host? Mount everything. Want a sandboxed environment for running less predictable tools? Expose only what's needed. The trust model should be a dial, not a switch.

A word of caution, though: this is a mitigation for accidents and non-deterministic tools, not a security boundary for running genuinely untrusted workloads. Kapsule containers share the host's Wayland, PulseAudio, and PipeWire sockets—that's a lot of attack surface if you're worried about malicious code. For truly untrusted workloads, VMs would be a much better fit, and Incus already supports those. It's not on my roadmap, but all the building blocks are there if someone wants to explore that direction.

New on the radar: exporting apps

Here's one I didn't see coming. aks asked about running a GUI application installed inside a container and having it show up on the host like a normal app. I realized... I didn't have that functionality at all.

The naive approach is straightforward enough: drop a .desktop file into ~/.local/share/applications that launches the app inside the container. But I really don't like that solution, and here's why:

  • Stale entries. If the container gets deleted, or Kapsule itself gets uninstalled, those .desktop files just sit there like ghosts. You click them, nothing happens, and now you're debugging why your app launcher is showing dead entries.
  • No ownership tracking. There's no built-in mechanism to say "this .desktop file belongs to this container, managed by Kapsule." If something goes wrong, there's no clean way to find and remove all the artifacts.

What I really want is a way to tie exported application entries to their owning container and to Kapsule itself. That way, when a container goes away, its exported apps go away too. Clean. Automatic. No orphans.

This might require changes to kbuildsycoca—the KDE system configuration cache builder—to support some kind of ownership or provenance metadata for .desktop files. I need to investigate whether that's feasible or if there's a better approach entirely. It's the kind of problem where the quick hack is obvious but the right solution requires some thought.

Taking a break (in theory)

chained to a desk

I'm going to do my best to not touch Kapsule until the weekend. I have a day job that I've been somewhat neglecting in favor of hacking on this, and my employer probably expects me to, you know, do the thing they're paying me for.

We'll see how good my self-control is.

Ever since C++20 introduced coroutine support, I was wondering how this could integrate with Qt. Apparently I wasn’t the only one: before long, QCoro popped up. A really cool library! But it doesn’t use the existing future and promise types in Qt; instead it introduces its own types and mechanisms to support coroutines. I kept wondering why no-one just made QFuture and QPromise compatible – it would certainly be a more lightweight wrapper then.

With a recent project at work being a gargantuan mess of QFuture::then() continuations (ever tried async looping constructs with continuations only? 🥴) I had enough of a reason to finally sit down and implement this myself. The result: https://gitlab.com/pumphaus/qawaitablefuture.

Example

#include <qawaitablefuture/qawaitablefuture.h>

QFuture<QByteArray> fetchUrl(const QUrl &url)
{
    QNetworkAccessManager nam;
    QNetworkRequest request(url);

    QNetworkReply *reply = nam.get(request);

    co_await QtFuture::connect(reply, &QNetworkReply::finished);
    reply->deleteLater();

    if (reply->error()) {
        throw std::runtime_error(reply->errorString().toStdString());
    }
    co_return reply->readAll();
}

It looks a lot like what you’d write with QCoro, but it all fits in a single header and uses native QFuture features to – for example – connect to a signal. It’s really just syntax sugar around QFuture::then(). Well, that, and a bit of effort to propagate cancellation and exceptions. Cancellation propagation works both ways: if you co_await a canceled QFuture, the “outer” QFuture of coroutine will be canceled as well. If you cancelChain() a suspended coroutine-backed QFuture, cancellation will be propagated into the currently awaited QFuture.

What’s especially neat: You can configure where your coroutine will be resumed with co_await continueOn(...). It supports the same arguments as QFuture::then(), so for example:

QFuture<void> SomeClass::someMember()
{
    co_await QAwaitableFuture::continueOn(this);
    co_await someLongRunningProcess();
    // Due to continueOn(this), if "this" is destroyed during someLongRunningProcess(),
    // the coroutine will be destroyed after the suspension point (-> outer QFuture will be canceled)
    // and you won't access a dangling reference here.
    co_return this->frobnicate();
}

QFuture<int> multithreadedProcess()
{
    co_await QAwaitableFuture::continueOn(QtFuture::Launch::Async);

    double result1 = co_await foo();
    // resumes on a free thread in the thread pool
    process(result1);

    double result2 = co_await bar(result1);
    // resumes on a free thread in the thread pool
    double result3 = transmogrify(result2);

    co_return co_await baz(result3);
}

See the docs for QFuture::then() for details.

Also, if you want to check the canceled flag or report progress, you can access the actual QPromise that’s backing the coroutine:

QFuture<int> heavyComputation()
{
    QPromise<int> &promise = co_await QAwaitableFuture::promise();
    promise.setProgressRange(0, 100);

    double result = 0;

    for (int i = 0; i < 100; ++i) {
        promise.setProgressValue(i);
        if (promise.isCanceled()) {
            co_return result;
        }
        frobnicationStep(&result, i);
    }
    co_return result;
} 

Outlook

I’m looking to upstream this. It’s too late for Qt 6.11 (already in feature freeze), but maybe 6.12? There have been some proposals for coroutine support on Qt’s Gerrit already, but none made it past the proof-of-concept stage. Hopefully this one will make it. Let’s see.

Otherwise, just use the single header from the qawaitablefuture repo. It an be included as a git submodule, or you just vendor the header as-is.

Happy hacking!

Caveat: GCC < 13

There was a nasty bug in GCC’s coroutine support: https://gcc.gnu.org/bugzilla/show_bug.cgi?id=101367 It affects all GCC versions before 13.0.0 and effectively prevents you from writing co_await foo([&] { ... }); – i.e. you cannot await an expression involving a temporary lambda. You can rewrite this out as auto f = foo([&] { ... }); co_await f; and it will work. But there’s no warning at compile time. As soon as the lambda with captures is a temporary expression inside the co_await, it will crash and burn at runtime. Fixed with GCC13+, but took me a while to figure out why things went haywire on Ubuntu 22.04 (defaults to GCC11).

The second maintenance release of the 25.12 series is with the usual batch of stability fixes and workflow improvements. Highlights of this release include fixes to various monitor issues and refactoring of the monitor dragging mechanism. See the changelog below for more details.

Kdenlive needs your support

Our small team has been working for years to build an intuitive open source video editor that does not track you, does not use your data, and respects your privacy. However, to ensure a proper development requires resources, so please consider a donation if you enjoy using Kdenlive - even small amounts can make a big difference.

For the full changelog continue reading on kdenlive.org.

Sunday, 8 February 2026

Minimalism came in like a wrecking ball somewhere around 2013. It delivered a terminal diagnosis to all but a few prevailing designs at the time. One of them, called Oxygen, had reigned supreme in KDE Plasma. As with many others, its demise was inevitable. Anyone aspiring to demonstrate that they were building something new and...... Continue Reading →

Saturday, 7 February 2026

Transitous is a project that runs a public transport routing service that aspires to work wold-wide. The biggest leaps forward in coverage happened in the beginning, when it was just a matter of finding the right urls to download the schedules from. Most operators provide them in the GTFS format, which is also used in Google Transit and a few other apps.

However, the number of readily available GTFS schedules (so called feeds) that we are not using yet is starting to become quite small. As evident when comparing with Google Transit, there are still a number of feeds that are only privately shared with Google. This is not great from a standpoint of preventing monopolies and also a major problem for free and open-source projects which don’t have the resources to discuss with each operator individually or to even buy access to the data from them. Beyond that case, there is still a suprisingly large number of places in the world that do not publish any schedules in a standardized format, and that is something that we can fix.

Source data comes in many shapes and forms, but the ingredients we’ll definitely need are:

  • the lines
  • stop times
  • stop locations
  • and service dates

Sometimes you can find a provider specific API that returns the needed information, or there is open data in a non-standard format. In the worst case, it might be necessary to scrape data out of the HTML of the website.

Some examples:

a stop time from the API of ŽPCG (Railway in Montenegro):

Example 1:

{
    "ArrivalTime" : "15:49:16",
    "DepartureTime" : "15:51:16",
    "stop" : {
        "Latitude" : 42.511829,
        "Longitude" : 19.203468,
        "Name_en" : "Spuž",
        "external_country_id" : 62,
        "external_stop_id" : 31111,
        "local" : 1,
    }
}

It is immediately visible that we get the stop times, in for some reason extreme precision. We also get coordinates for the location, which makes conversion to GTFS much easier. Unfortunately the coordinates from this dataset are not exactly great, and can easily be off by multiple kilometers, but they nevertheless provide a rough estimate that we can improve on by matching them to OpenStreetMap.

The railway-data enthusiasts will also notice that we get a UIC country code and a stop code, which we can concatinate to get a full UIC stop identifier. We can make use of that for OSM matching later on.

Example 2:

<ElementTrasa Ajustari="0" CodStaDest="27888" CodStaOrigine="23428" DenStaDestinatie="Ram. Budieni"
    DenStaOrigine="Târgu Jiu" Km="1207" Lungime="250" OraP="45180" OraS="45300" Rci="R" Rco="R" Restrictie="0"
    Secventa="1" StationareSecunde="0" TipOprire="N" Tonaj="500" VitezaLivret="80"/>

This example is from open data for railways in Romania. Unfortunately this one does not give us coordinates, and the fact that the fields are in abbreviated Romanian doesn’t make it too easy to understand for someone like me who does not speak any vaguely related language. However looking at the numbers, we can figure out that OraP and OraS are seconds and provide the departure and arrival times. However here, the data does not model the times at stops, but the transitions between the stops, so some more reshuffling is necessary.

Example 3:

{
    "ArrivalTimes" : "12:35, 13:37, 14:02, 14:21, 14:52, 14:27, 15:04, 15:50, 16:14, 16:39, 17:08, 17:36, 18:55, 19:03, 19:12, 20:05, 20:33, 21:12, 21:47",
    "Classes" : "2",
    "DepartureTimes" : "12:35, 13:38, 14:03, 14:22, 15:12, 14:42, 15:29, 15:51, 16:15, 16:40, 17:33, 17:37, 18:57, 19:08, 19:13, 20:06, 20:34, 21:13, 21:47",
    "Route" : "Vilnius-Krokuva",
    "RouteStops" : "Vilnius, Kaunas, Kazlų Rūda, Marijampolė, Mockava, Trakiškė/Trakiszki, Suvalkai/Suwałki, Augustavas/Augustów, Dambrava/Dąbrowa Białostocka, Sokulka/Sokółka, Balstogė/Białystok, Balstogė (Žaliakalnio stotis) / Białystok Zielone Wzgórza, Varšuva (Rytinė stotis)/ Warszawa Wschodnia, Varšuva (Centrinė stotis)/ Warszawa Centralna, Varšuva (Vakarinė stotis)/ Warszawa Zachodnia, Opočnas (Pietinė stotis)/Opoczno Południe, Vloščova (Šiaurinė stotis)/Włoszczowa Północ, Mechuvas/Miechów, Krokuva (Pagrindinė stotis)/ Kraków Główny",
    "RunWeekdays" : "1,2,3,4,5,6,7",
    "Spaces" : "WHEELCHAIR, BICYCLE",
    "TrainNumber" : "33/141"
}

This example is from the, to my knowledge, only source of semi-machine-readable information on railway timetables in Lithuania. While json is straightforward to parse, this one for some reason does not use json arrays, but comma-separated lists. We can still work with this of course, until a stop appears whose name contains a comma. Oh well. Once again, no coordinates are provided. While it is tempting to think this should be easier to convert than xml in Romanian, this format has some more hidden fun. If you have been to the area the line from the example operates in, you might already have noticed that the time zone changes between Lithuania and Poland. Unfortunately, there is no notice of that in the data, just a randomly backwards-jumping arrival and departure time.

To work with this, we first need to match the stop names to coordinates, then figure out the time zones from that, and then convert the stop times.

Matching stations to locations

OpenStreetMap is the obvious choice for this. It is fairly easy to query the station locations, but matching the strings to the node in OSM is not trivial. There are often variations in spelling, particularly if the data covers neighbouring countries with different languages. The data may also have latinized names, while the country usually uses a different script and so on.

Since this problem comes up repeatedly, I am slowly improving my rust library (gtfs-generator) for this, so it can hopefully handle most of these cases automatically at some point. It aims to be very customizable, so the matching criteria needs to be supplied by the library user. The following example matches a stop if it has a matching uic_ref tag, which is a strong identifier. If no node has such a matching tag, all nodes in the radius of 20km are considered if their name is either a direct match, an abbreviation of the other spelling, similar enough or has matching words. The matching radius can be overridden in each query, so if nothing is known yet, the first guess can be the middle of the country with a large enough radius. As soon as one station is known, the ones appearing on the same route must be fairly close. The matching quality strongly depends on making a good guess of the distance from the previous stop, as it greatly reduces the risk of similarly named stations being mismatched.

Since OpenStreetMap provides different multi-lingual name tags, the order that these should be considered in needs to be set as well.

The code for matching will look something like this:

let mut matcher = osm::StationMatcherBuilder::new()
    .match_on(osm::MatchRule::FirstMatch(vec![
        osm::MatchRule::CustomTag {
            name: "uic_ref".to_string(),
        },
        osm::MatchRule::Both(
            Box::from(osm::MatchRule::Position {
                max_distance_m_default: 20000,
            }),
            Box::from(osm::MatchRule::FirstMatch(vec![
                osm::MatchRule::Name,
                osm::MatchRule::NameAbbreviation,
                osm::MatchRule::NameSimilar {
                    min_similarity: 0.8,
                },
                osm::MatchRule::NameSubstring,
            ])),
        ),
    ]))
    .name_tag_precedence(
        [
            "name",
            "name:ro",
            "short_name",
            "name:en",
            "alt_name",
            "alt_name:ro",
            "int_name",
        ]
        .into_iter()
        .map(ToString::to_string)
        .collect(),
    )
    .transliteration_lang(TransliterationLanguage::Bg)
    .download_stations(&["RO", "HU", "BG", "MD"])
    .unwrap();
    
    // Parse input

    let station = matcher.find_matching_station(&osm::StationFacts {
        name: Some(name),
        pos: Some(previous_coordinates.unwrap_or((46.13, 24.81))), // If we know nothing yet, bias to the middle of Romania, so we at least don't end up in the wrong country
        max_distance_m: match (previous_coordinates, previous_time, atime) {
            // We have previous coordinates, but nothing for this station. Base limit on max reachable distance at reasonable speed
            (Some(_prev_coords), Some(departure), Some(arrival)) => {
                let travel_seconds = arrival - departure;
                Some(travel_seconds * 70) // m/s
            }
            // No previous location known
            _ => Some(800000),
        },
        values: HashMap::from_iter([("uic_ref".to_string(), uic_ref.clone())]),
    });

For now, until I’m somewhat certain about the API, you’ll need to use the git repository directly to use the OSM matching feature.

Finally writing the GTFS file

After all the ingredients are collected, the actual GTFS conversion should be fairly easy. We now need to sort the data we collected into the main categories of objects represented by GTFS, routes, trips, stops, and stop_times.

Every trip needs to have a corresponding route. The exact distinction between different routes depends on the specific transit system. In the simplest case, if multiple buses operate with the same line number on the same day, they would belong to the same route. Each time the bus operates per day, a new GTFS trip starts.

If the system does not have the concept of routes, every trip simply is its own route. This is for example what Deutsche Bahn does for ICE trains, where each journey has it’s own train number.

The code for building the GTFS data looks somewhat like this:

    let mut gtfs = GtfsGenerator::new();

    // parse input

    gtfs.add_stop(gtfs_structures::Stop {
        id: stop_time.station_code.to_string(),
        name: Some(stop_time.station_name.to_string()),
        latitude: coordinates.as_ref().map(|(lat, _)| *lat),
        longitude: coordinates.as_ref().map(|(_, lon)| *lon),
        ..Default::default()
    })
    .unwrap();

    gtfs.add_stop_time(gtfs_structures::RawStopTime {
        trip_id: trip_id.clone(),
        arrival_time: Some(atime.unwrap_or(dtime)),
        departure_time: Some(dtime),
        stop_id: stop_time.station_code.to_string(),
        stop_sequence: stop_time.sequence,
        ..Default::default()
    })
    .unwrap();
    
    gtfs.write_to("out.gtfs.zip").unwrap();

Validating the result

A new GTFS feed is rarely perfect on the first try. I recommend running it through gtfsclean first. After all obvious issues are fixed (missing fields, broken references), you can use the validator of the French government and the canonical GTFS validator. It is worth using both, as they check for slightly different issues.

Once all critical errors reported by the validators are fixed, you can finally test the result in MOTIS. You can get a precompiled static binary from GitHub Releases. Afterwards create a minimal config file using ./motis config out.gtfs.zip. The API on it’s own is not too useful for testing, so add

server:
  web_folder: /path/to/ui/directory

to the top of the file to make the web interface available.

Make sure to also enable the geocoding option, so you can search for stops.

Now all that’s needed is loading the data and starting the server:

./motis import
./motis server

You should now be able to search for your stops and find routes:

MOTIS showing a connection between Vilnius and Riga

Publishing

Once it is ready, the GTFS feed needs to be uploaded to a location that provides a stable url even if the feed is updated. The webserver should also support the Last-Modified-header, so the feed can be downloaded only when needed. A simple webserver serving a directory like nginx or apache works well here, but something like Nextcloud works equally well if you already have access to an instance of it.

Since the converted dataset needs to be regularly updated, I recommend setting up a CI pipeline for that purpose. The free CI offered by gitlab.com and GitHub is usually good enough for that. I recommend setting up pfaedle in the pipeline, to automatically add the exact path the vehicles take based on routing on OpenStreetMap data.

Once you have a URL, you can add it to Transitous and places where other developers can find it, like the Mobility Database

If you are interested in some examples of datasets generated this way, check out the Mobility Database entries for LTG Link and ŽPCG. You can find a list with some examples of feeds I generate here, including the generator source code based on the gtfs-generator crate.

You can always ask in the Transitous Matrix channel in case you hit any roadblocks with your own GTFS-converter projects.
This is a sequel to my first blog where I’m working on fixing a part of docs.kde.org: PDF generation. The documentation website generation pipeline currently depends on docs-kde-org, and this week I was focused on decoupling it.

Moving away from docs-kde-org

I began by copying the script that builds the PDFs in docs-kde-org to ci-utilities as a temporary step towards independence.

I then dropped the bundled dblatex for the one present in the upstream repos, wired up the new paths and hit build. To no one’s surprise, it failed immediately. The culprit here was the custom made kdestyle latex style. As a temporary measure, I excluded it to get PDFs to generate again, however several (new) locales broke.

So the pipeline now worked, albeit, partially.

(Commit 17bbe090) (Commit 3e8f8dc9)

Trying XeTeX

Most non-ASCII languages (Chinese, Japanese, Korean, Arabic, etc) are not supported for PDF generation because of wonky unicode support in pdfTeX (the existing backend driver that converts LaTeX code to a PDF)

So I switched the backend to XeTeX to improve the font and language handling. Now I’m greeted with a new failure :D

1
xltxtra.sty not found

xltxtra is a package used by dblatex to process LaTeX code with XeTeX. Installing texlive-xltxtra fixed this, and almost everything built (except Turkish)

(Commit 7ede0f94)

The deprecated package rabbit hole

While installing xltxtra, I noticed that it was deprecated and mostly kept for compatibility. So I tried replacing it with modern alternatives (fontspec, realscripts, metalogo).

Back to xltxtra.sty not found

At the point I looked at the upstream dblatex code and found references to xltxtra in a Latex style file and in the XSL templates responsible for generating the latex.

I experimented with local overrides, but the dependency was introduced during the XSLT stage so it isn’t trivial to swap out.

Clearer mental model

A very good outcome from the experiments is that I now understand the pipeline much better

1
DocBook XML -> XSLT Engine -> LaTeX Source -> XeLaTex -> PDF

XSL files are templates for the XSLT engine to convert the docbooks to latex and the problem is probably in one of these templates

Decision with mentor

After discussion, Johnny advised me to

  • Use texlive-xltxtra for now
  • Open an upstream issue
  • And that fixing dblatex itself is outside our scope

So I went ahead and filed the issue https://sourceforge.net/p/dblatex/bugs/134/. Now we keep moving forward while also documenting the technical debt.

Locales experiment

I temporarily re-enabled previously excluded locales (CJK etc) to see what happens. Unfortunately most of them didn’t generate silently. I’m still unsure about this part and the behavior might differ in other projects, so I’ll revisit this later.

(Commit 04b698a5)

kdestyle strikes back

Now I fed the absolute path of kdestyle to dblatex (to maintain PDF output parity) which introduced a new set of errors

  • Option clash for graphicx
  • conflicting driver options in hyperref (dvips, pdftex)

These seem to originate from the style file and is the next major thing to resolve.

(Commit 7ede0f94)

Improved Git skills

I also had a self inflicted problem this week. My feature branch diverged from master and I merged instead of rebasing. As a result the history got messed up. I fixed it by:

  • dropping the merge commit
  • rebasing properly
  • force pushing the cleaned branch

Lessons learnt. Working with open source projects has really made git less intimidating.

Where things stand

Right now

  • we can build with XeTeX
  • we rely on texlive-xltxtra
  • most locales work (except Turkish of course)
  • kdestyle introduces some problems

Also here’s a before vs after of the generated PDFs (the end goal would be to make both of them look identical)

Honestly I don’t feel like I got much accomplished but the understanding gained should make future changes much faster (and safer :D)

Dev logs log 1, log 2, log 3, log 4

Edit (09-02-2026): Added links to relevant commits based on feedback received

In my first week of Season of KDE, I managed to stop the Lokalize menubar from jumping around by enforcing a strict "Global Skeleton" in the XML files. We gave tabs empty menus just to hold space and keep the layout from shifting. It solved the jumping bug perfectly, but it introduced a new, slightly awkward UX problem.

Because those empty menus were technically just sitting there to hold space, they were still clickable. If you were in the Project Overview tab and clicked "Sync," nothing happened. No dropdown appeared, it was just a clickable menu that did nothing. It didn't crash the app, but it felt unfinished. My mentor, Finley, pointed this out and showed me how Kate handles this by greying out unusable actions. To see if we could replicate that, i built a massive "Complete Menu Action Comparison" matrix to map every action across every tab.

The matrix proved we couldn't just copy Kate. Lokalize menus change drastically depending on context-the Edit menu has 20 actions in the Editor, but only one (Find) in the Project Overview. Showing 19 greyed-out, irrelevant actions would just clutter the ui. Instead, Finley suggested a better approach: what if we grey out the menu headers themselves right on the menubar? Figuring out how to code that became my primary goal for week 3.

While analyzing the menu architecture, we also discussed whether to move all menu definitions into one centralized file, dropping the individual KXMLGUIClient .ui.rc files. I analyzed how other major KDE projects like Kate, Okular, Dolphin, and Ark to see how they handled it.

I found out that every major KDE app keeps a distributed model and merges dynamically. Centralizing Lokalize would force us into manually managing visibility and shortcuts, creating a fragile refactor. I shared this with Finley, and we agreed to stick to the distributed approach.

Also when i was working with .rc files, I found a graveyard of "ghost actions"-XML entries with zero implementation in the C++ backend. I drafted an email to the KDE translators' mailing list asking for direct feedback on which actions they actually use in their workflows so i can decide which actions i need to implement or remove.